Tools, resources and prompts together
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
One server, three controllers
Larkspur wants one server to support model-selected searches, engineer-selected data and reusable instructions. You will follow a complete tool-resource-prompt session and inspect how shared temporary files can mix users' work.
Step 1: Assign control to the primitive that owns it
T12.1 introduced the three things a server can offer. The Job Market Explorer server uses all three at once, which shows how they divide the work. The project's presentation names who controls each: tools are "Model-controlled", resources "Application-controlled" and prompts "User-controlled".
| Primitive | In this server | Who triggers it | Side effects |
|---|---|---|---|
| Tool | search_jobs(role, location, max_results=5), save_job(job_id, salary=None) |
The model, when it decides to | Calls the JSearch API on RapidAPI; writes JSON files |
| Resource | resume://default (text from resume/resume.pdf), jobs://saved (every saved job as Markdown) |
The application, usually because the user attached it | None: they only read |
| Prompt | analyze_job_market(role, location, num_jobs=5), personalized_job_recommender(), create_match_report() |
The user, by picking it | None: they return instructions |
Step 2: Trace data through the server files
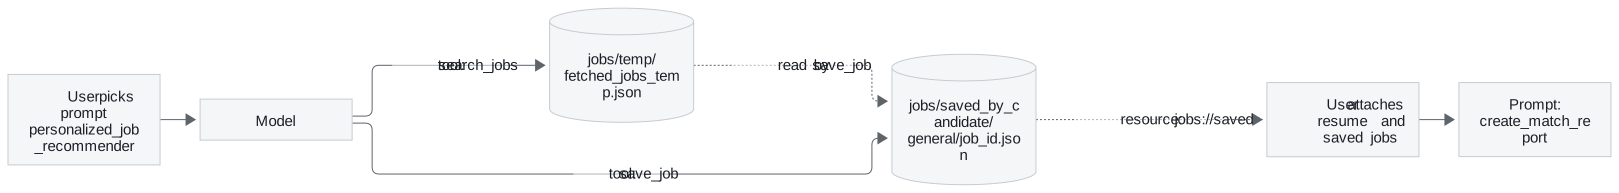
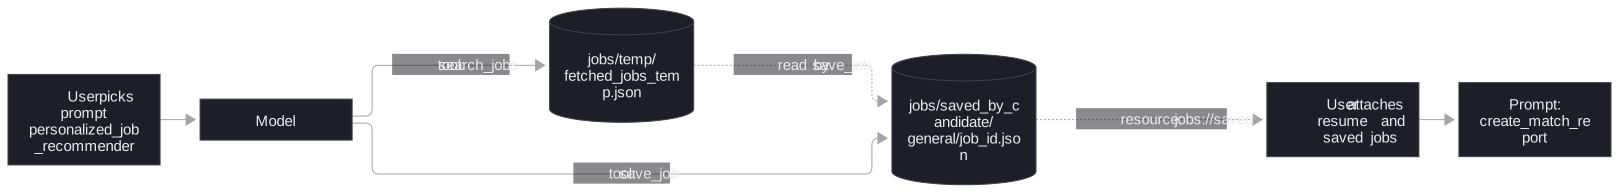
A full session uses all three in order, and the pieces meet in files on the server's disk:
Step 3: Distinguish instructions from executed actions
The prompts are scripts for the model: personalized_job_recommender says to read the resume, "Call job search mcp tool", then "Optionally call save job mcp tool on top matches". create_match_report starts "Given the attached jobs data and resume", so it only works once the user has attached both resources. The server writes the workflow; the host has to support every step of it.
Step 4: Check which primitives the adapter loads
Hosts differ in how much of that they support. In langchain-mcp-adapters 0.3.2, load_mcp_tools and MultiServerMCPClient.get_tools() load tools only. Resources come from client.get_resources(...) and prompts from client.get_prompt(...), and the application has to fetch them and put them in the conversation itself. A LangGraph app that only loads tools sees 2 of this server's 7 features, and create_match_report has nothing attached to read.
Step 5: Find the hidden dependency between tool calls
Two design points the server gets wrong for anything beyond one user:
- Hidden coupling between tools.
save_jobonly works aftersearch_jobs, because it reads the single filefetched_jobs_temp.json. Two users of a shared server overwrite each other's search, andsave_jobsaves a job from someone else's results or reports the id as not found. - Paths relative to the working directory.
BASE_DIR = Path(".")putsjobs/andresume/wherever the server process starts. The Claude Desktop entry passesuv --directory, which sets it (40.2); anchor paths onPath(__file__).parentinstead, as the 06 and 07 servers do.
Try it yourself
Let two users search different jobs before either saves one. Inspect the single fetched_jobs_temp.json dependency and identify how the second search can replace the first user's candidates. Specify per-user or per-request storage before assuming a shared server preserves the sequence implied by the prompt.
Practice notebook
Run the complete implementation from the practice material after checking the trace or calculation above. Use its stated environment for live model or server calls; recorded model choices and timings are observations, not guaranteed outputs.
Continue learning
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| MCP tools resources and prompts | Open on GitHub | Run locally |
Key Takeaways
- Tools are model-controlled and may have side effects; resources are application-controlled and only read; prompts are user-controlled and return instructions.
- Many hosts load tools only. The application must fetch resources and prompts itself, or a prompt that expects attached data has nothing to read.
- Avoid hidden coupling through shared temp files and paths relative to the working directory. Anchor paths on
Path(__file__).parentand keep per-user state apart.
Check yourself
1. Who triggers each of the Job Market Explorer server's three primitives, and which of them have side effects?
Tools are model-controlled and have side effects: search_jobs calls the JSearch API and save_job writes JSON files. Resources are application-controlled and only read. Prompts are user-controlled and return instructions, so they change nothing.
2. A LangGraph app loads this server with get_tools only. How much of the server does it see, and what happens to the match report?
2 of its 7 features: in langchain-mcp-adapters 0.3.2, get_tools() loads tools only. create_match_report starts "Given the attached jobs data and resume", so it has nothing to read unless the app fetches the resources with client.get_resources(...) and the prompt with client.get_prompt(...) and puts them in the conversation itself.
3. Two users share one Job Market Explorer server, and one of them saves a job that came from the other's search. Why?
save_job only works after search_jobs, because it reads the single file fetched_jobs_temp.json. A second user's search overwrites the first user's, so save_job saves a job from someone else's results or reports the id as not found. That hidden coupling between tools breaks as soon as there is more than one user.