Environment setup and a complete RAG system
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
Grounded generation
What you'll learn
- Trace a complete RAG system from two kinds of source to an answer.
- Explain the three parts of a grounded prompt and what each one prevents.
- Diagnose a chain whose answers cannot be checked, and an embedding call that embeds characters.
- Test grounding with questions the corpus cannot answer.
Lessons T6.1 to T6.3 made retrieval find more, rank better and fit the budget. T6.4 turns a retrieval pipeline into a system someone can rely on, and starts by building one end to end.
A Larkspur customer asks Does Larkspur offer a free tier? The handbook says nothing about one. A chain that retrieves five chunks and asks the model to "answer the question" gets a fluent reply anyway, drawn from what the model knows about other hosting providers. The answer reads as policy, and it is invented.
Grounded generation means the answer comes from evidence the system retrieved for this question, and the model is told to use nothing else. Notebook 01b builds the whole pipeline:
| Stage | What 01b does |
|---|---|
| Load | A JSON-lines loader reads a Wikipedia sample one article per document, keeping title, id and source as metadata; a PDF loader reads every PDF in a sample folder |
| Split | 3,500-character chunks with 200 of overlap for the PDFs; Wikipedia articles stay whole |
| Embed | text-embedding-3-small, 1,536 dimensions |
| Store | Chroma, persisted to disk, set to cosine distance; without that setting Chroma uses Euclidean distance (lesson 4 of T5.1) |
| Retrieve | Similarity search, k = 5 |
| Generate | A small chat model at temperature 0, with a prompt that restricts it to the retrieved context |
Table 1: The pipeline in 01b.
The chain itself is three steps:
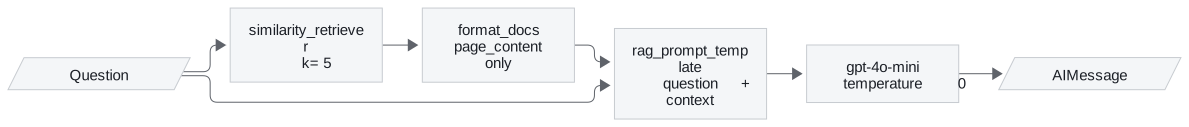
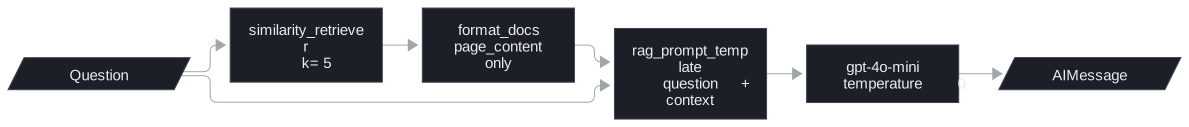
Figure 1: The 01b chain. The retrieved chunks become plain text inside the prompt.
Grounding rests on three things, and 01b's prompt has all three:
| Part | 01b's wording |
What it prevents |
|---|---|---|
| Evidence for this question | The five retrieved chunks | The model answering from the whole of its training |
| A limit | "Answer the following question using only the following pieces of retrieved context" | Blending in outside knowledge |
| A way out | "If the answer is not in the context, do not make up answers, just say that you don't know" | A forced answer when the evidence is missing |
Table 2: The three parts of a grounded prompt.
The third part is the one most often left out. Without a permitted refusal, a model asked about something the context lacks answers from what it learned in training. We call that an ungrounded fill: the free-tier answer above.
Here is what grounding should produce on two Larkspur questions (Illustrative: expected answers, not a recorded run):
| Question | Retrieved evidence | Grounded answer |
|---|---|---|
| Can I export my data after I cancel my plan? | export, retention |
Yes, within 30 days, from Settings, then Data |
| Does Larkspur offer a free tier? | Nothing relevant | I don't know |
Table 3: Grounded answers, with and without evidence.
Whether a given model complies is a property you test. Put questions with no answer in the golden set and count the refusals. The instruction does not guarantee compliance either: a model can still blend in outside knowledge or misread a chunk, and T9.2 and T9.5 add a second call that grades the answer against its evidence.
What this chain throws away
01b's formatting step joins the chunks' text and nothing else, so the title, id and source in metadata never reach the model, and the chain returns only the model's message. The answer may be grounded, but nobody can check it: there is no list of chunks, and no way to say which one a sentence came from. We call this formatted-away sources. Lesson 2 of T6.4 keeps both.
A setup trap
01b embeds the string "Hello, world!" with the batch method meant for a list of documents, and gets back 13 vectors. A Python string is iterable, so each of its 13 characters is embedded on its own. The single-query method, or a one-item list, gives one 1,536-dimension vector.
Pitfall: character embedding. The same mistake inside an indexing loop embeds characters and stores them without an error. Check that the number of vectors equals the number of chunks after every indexing run.
The optional 01c notebook builds the same pipeline on FAISS from one climate-change PDF, with 1,000-character chunks, 200 of overlap and k = 2, and reconstructs the index matrix to show its shape: one row per chunk, 1,536 columns.
In practice: a grounded Larkspur assistant
- Use all three parts of Table 2 in the prompt, including the way out.
- Add unanswerable golden questions (free tier, GPU servers) and track the refusal rate.
- Count vectors against chunks after indexing.
- Keep the chunks in the output, which lesson 2 of T6.4 shows how to do in one retrieval.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| Setup | Open on GitHub | Open in Colab |
| Build a simple RAG system | Open on GitHub | Open in Colab |
| Simple RAG PDF (optional) | Open on GitHub | Open in Colab |
Key Takeaways
- Grounding needs three things in the prompt: evidence retrieved for this question, an instruction to use only that evidence, and permission to say "I don't know". Without the last, the model fills gaps from training (an ungrounded fill).
- The instruction does not guarantee compliance. Put questions with no answer in the golden set and count the refusals.
- A chain that formats only the chunk text and returns only the answer cannot be checked (formatted-away sources). Keep the chunks and their metadata if anyone needs to verify a sentence.
Check yourself
1. A Larkspur assistant answers "Does Larkspur offer a free tier?" with a confident description of one. Which part of a grounded prompt is missing?
Most likely the way out: permission to say "I don't know" when the answer is not in the context. Without it, a model whose evidence lacks the answer fills the gap from training. Add it, then test with unanswerable golden questions and count the refusals, because the instruction alone does not guarantee compliance.
2. The 01b chain's answers are grounded, but a reviewer cannot tell which chunk any sentence came from. Why?
The formatting step joins only the chunks' text, so titles, ids and sources never reach the model, and the chain returns only the model's message. There is no list of chunks to check against. Keeping the retrieved chunks in the output, as lesson 2 of T6.4 does, makes the answer checkable.
3. Embedding "Hello, world!" returns 13 vectors. What went wrong, and why is it dangerous in an indexing loop?
The batch method expects a list of strings, and a Python string is iterable, so each of its 13 characters was embedded separately. In an indexing loop the same mistake stores character vectors without an error. Use the single-query method or a one-item list, and check that vectors equal chunks after indexing.