Parallel agents, async nodes and streaming
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
Map-reduce / async
What you'll learn
- Explain how LangGraph runs parallel branches in supersteps, and why the slowest branch sets the pace.
- Choose a join that waits for every branch, and a reducer for every key that parallel branches share.
- Use
Sendfor a fan-out whose size is known only at run time.- Compare what
asyncnodes,astreammodes and a concurrency cap change, and when parallelism buys nothing.
Lesson 4 of T11.2's ensemble ran three analysts at once without taking the machinery apart. This lesson is that machinery.
Larkspur's assistant receives a compound question: "I'm cancelling my annual plan after this week's outages. Can I get a full refund, how long will it take, can I still export my data, and do I get credits for the outages?" It splits into four sub-questions with independent evidence. Answered one at a time, the reply takes as long as every model call added together. Answered in parallel with the wrong join, the first reply goes out with nothing about outage credits.
An agent spends almost all of its time waiting: for a model, a search, a database. Three agents that each wait one second take 3 s one after another and 1 s together, because the waits overlap. Nothing runs faster. The async notebook measures exactly that with a one-second sleep standing in for a model call, and a scratch run prints 3.00 s and 1.00 s.
Three of the four sub-questions are answered directly. The outage one first rewrites "outages" into the handbook's own words (availability, service credits), because TF-IDF missed that evidence in T5.1:
- Superstep 1: plan splits the question into four sub-questions, 0 to 0.4 s.
- Superstep 2: four edges out of plan start all four nodes at once. updates streams each one as it finishes, refund_timing first at 1.2 s.
- rewrite is done at 0.9 s, but superstep 2 ends only when export finishes at 1.6 s, so credits waits 0.7 s.
- Superstep 3: credits answers the rewritten outage question, 1.6 to 2.6 s.
- The list edge opens only when all four sub-answers are in. Separate edges would have run synth once already, in superstep 3, with three.
- Superstep 4: synth writes the reply from four sub-answers, 2.6 to 3.4 s, against 5.7 s one at a time.
Figure 1: The lab's graph. A planner fans out to four branches, and the outage branch is one node longer than the rest.
Supersteps and the barrier
LangGraph runs a graph in supersteps. In each superstep it runs every node that the previous superstep triggered, waits for all of them, applies their state updates together, and only then works out what runs next. Several edges out of one node, a fan-out, put all their targets in the same superstep, and they run in parallel: async def nodes on the event loop, plain def nodes in a thread pool.
The parallel notebook proves the layout with model-free stub nodes and a debug stream that reports the superstep of every task. A scratch run on a planner, three searchers and a report gives:
| Superstep | Nodes that ran |
|---|---|
| 1 | plan |
| 2 | search_db, search_docs, search_web |
| 3 | report |
Table 1: Superstep layout of a one-planner, three-searcher fan-out, from a scratch run (LangGraph 1.2.18).
The barrier at the end of a superstep costs time when branches have different lengths. The lab gives each node a fixed stub latency:
| Node | plan | refund_window | refund_timing | export | rewrite | credits | synth |
|---|---|---|---|---|---|---|---|
| Seconds | 0.4 | 1.0 | 0.8 | 1.2 | 0.5 | 1.0 | 0.8 |
Table 2: The lab's stub latencies.
In Figure 1, rewrite finishes at 0.9 s, but credits cannot start until the whole superstep ends at 1.6 s, when export (the slowest, 1.2 s) finishes. The outage branch waits 0.7 s for work it does not depend on. We call this the barrier tax. Moving the rewrite inside the credits node keeps every branch one node long, and the answer lands at 2.7 s instead of 3.4 s.
Joins that wait for every branch
A join is a node with several incoming branches. With separate edges from each branch, it runs once for every superstep in which one of its predecessors finished. The parallel notebook builds one unequal-branch graph three ways: branch a is one node long, branch b1 then b2 is two. A scratch run counts the join's runs:
| Join style | Join runs | What each run saw | Nodes per superstep |
|---|---|---|---|
| Separate edges | 2 | a, then a + b2 |
{a, b1}, {b2, join}, {join} |
List edge from a and b2 |
1 | a + b2 |
{a, b1}, {b2}, {join} |
defer=True on the join |
1 | a + b2 |
{a, b1}, {b2}, {join} |
Table 3: One graph, three join styles, from a scratch run of the notebook's stub graphs.
The first row is the half-evidence answer. In the lab's graph the separate-edges synthesizer runs in superstep 3 with 3 of 4 sub-answers, writes a reply with nothing about outage credits, and runs again after credits.
- A list edge waits for every node it names. Use it when you know the predecessors at build time. If a conditional edge skips one of them, the join never runs.
defer=Trueholds the join until the run has nothing else to do. It also suits branches chosen at run time.
A model-free test like Table 3 counts the synthesizer's runs and keeps a fixed join fixed.
Fan-out sized at run time
Fixed edges cannot express a fan-out whose size is known only at run time: one branch per document, or one per sub-question when the decomposer (T6.2) returns three for one question and five for the next. A routing function that returns a list of Send objects can. Each Send names a node and a private input for it:
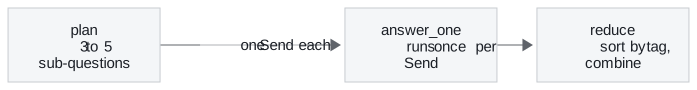
Figure 2: Map-reduce with Send. All the answer_one runs land in one superstep.
An operator.add reducer collects the results. Branches can finish in any order, and the reduce step sorts them by their tag before combining. The parallel notebook maps an LLM summary over three documents this way and counts one map branch per document. A fourth document adds a fourth branch with no change to the graph.
Async nodes and streaming
Making nodes async def and awaiting the graph changes nothing about which nodes are parallel. Edges from one source decide that, and a chain of async nodes still runs in order. What async adds is overlap on one event loop, and astream lets you watch it:
| Stream mode | Emits | Use it for |
|---|---|---|
updates |
One event per node, as that node finishes | Progress: "the refund branch is done" |
values |
The full state: the input, then once per superstep | Debugging the shared state |
messages |
Model output token by token, tagged with the node | Showing two agents writing at once |
Table 5: What each stream mode reports.
In the async notebook three agents wired to START sleep 1.0, 1.5 and 0.5 s. A scratch run gives:
| Time | updates reports |
values reports |
|---|---|---|
| 0.0 s | State with 0 notes | |
| 0.5 s | hydro finished | |
| 1.0 s | solar finished | |
| 1.5 s | wind finished | State with 3 notes |
Table 6: The same run through two stream modes. The team takes 1.50 s against 3.0 s for the sum.
updates reports in finish order, which is the proof the agents ran together. values stays silent between the two snapshots, because all three agents share one superstep.
In the lab, with the rewrite inside the agent node, the first sub-answer (refund_timing) streams through updates at 1.2 s. values stays silent until the superstep ends at 1.9 s, when credits (1.5 s with its rewrite) finishes. The interactive lab runs this graph with the stub latencies of Table 2 and draws every superstep. Its schedule was checked against LangGraph 1.2.18 running the same graph with sleeps at every setting:
| Setting in the lab | Answer lands | Synthesizer runs | Supersteps |
|---|---|---|---|
| One at a time, rewrite as its own node | 5.7 s | 1 | 7 |
| In parallel, rewrite as its own node, separate edges | 3.4 s | 2 (the first saw 3 of 4) | 4 |
In parallel, rewrite as its own node, list edge or defer=True |
3.4 s | 1 | 4 |
| In parallel, rewrite inside the agent | 2.7 s | 1 | 3 |
In parallel, rewrite inside the agent, max_concurrency 2 |
3.7 s | 1 | 3 |
In parallel, rewrite inside the agent, max_concurrency 1 |
5.7 s | 1 | 3 |
In parallel, rewrite as its own node, separate edges, max_concurrency 1 |
6.5 s | 2 | 4 |
Table 7: The lab's schedule at seven settings.
max_concurrency in the run config caps how many tasks run at once, which is how you stay under a provider's rate limit. LangGraph starts a superstep's tasks in node-name order, and under a cap the later names wait for a free slot. At a cap of 2, credits and export start first, and the two refund branches wait for a free slot. At a cap of 1 the parallel graph takes as long as the chain. With separate edges it takes longer, 6.5 s against 5.7 s, because the synthesizer still runs twice.
When parallelism buys nothing
- A chain. If the writer needs the researcher's output, it cannot start early. The async notebook's three dependent one-second steps take 3.00 s, async or not.
- A single agent. One agent waiting is one wait. Streaming can still show progress, but there is no time to win.
- Fast local work. Arithmetic and string handling are work, not waiting. Async adds overhead to them.
Whole runs can overlap too. Gathering three complete team runs on one event loop takes 1.50 s in a scratch run, against about 4.5 s one after another, with no change to the graph. Inside a running event loop, such as a notebook, await the graph directly: starting a second loop there fails.
In practice: the compound refund question
- Plan the four sub-questions, and dispatch them with
Sendwhen the decomposer's count varies. - Keep branches level: do the outage rewrite inside the credits agent and avoid the barrier tax.
- Join once: a list edge into the synthesizer, or
defer=Truewhen branches are chosen at run time. - Reduce the sub-answers with
operator.addand sort them by tag. - Stream
updatesto show each sub-answer as it lands, starting at 1.2 s in the lab. - Cap concurrency to the provider's rate limit, and price the cap in latency: 2.7 s becomes 3.7 s at a cap of 2.
T11.3 builds full multi-agent applications on these pieces, including a research system that dispatches a variable number of workers with Send and streams the run.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| Parallel agents | Open on GitHub | Open in Colab |
| Async multi agent streaming | Open on GitHub | Open in Colab |
Key Takeaways
- Parallel agents overlap their waits and run no faster: three one-second waits take 1 s together against 3 s in sequence. A chain, a single agent or fast local work gains nothing.
- LangGraph runs fan-out targets in one superstep and waits for all of them before the next. Keep branches the same length, and join with a list edge or
defer=Trueso the join runs once with every input. - Give any key that several nodes write in one superstep a reducer, or LangGraph raises
InvalidUpdateError. UseSendfor fan-outs sized at run time, andmax_concurrencyto stay under rate limits.
Check yourself
1. Three agents that each wait one second finish in about one second together. Why, and what does making nodes async not change?
The waits overlap, and nothing runs faster. Edges from one source put nodes in the same superstep, and that is what makes them parallel. Making nodes async def adds overlap on one event loop but does not change which nodes are parallel. A chain of async nodes still runs in order.
2. In the lab, moving the rewrite inside the credits node brings the answer from 3.4 s to 2.7 s. Where does the saving come from?
As its own node, rewrite finishes at 0.9 s, but credits cannot start until the superstep ends at 1.6 s, when export finishes. The outage branch pays a 0.7 s barrier tax for work it does not depend on. Inside one node, every branch is one node long and that wait disappears.
3. The synthesizer writes a reply with nothing about outage credits, then runs a second time. What causes this, and how do you fix it?
The join uses separate edges, and it runs once for every superstep in which a predecessor finished. Its first run saw 3 of 4 sub-answers. Use a list edge when the predecessors are known at build time, or defer=True when branches are chosen at run time. A list edge never runs if a conditional edge skips one of its named nodes.