Index operations: create, query, update, delete, persist
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
Stable IDs and the missing update
What you'll learn
- Explain the five operations every vector store supports, and why an update is a delete plus an insert.
- Design chunk IDs that make re-ingestion overwrite instead of duplicate.
- Diagnose a threshold that rejects everything, and a reopened store that silently returns nothing.
- Apply startup checks that turn silent store failures into errors.
T5.4 chose the embedding model and its dimensions. This module stores the vectors, and a store has more jobs than search: it must add, update and delete entries without leaving copies behind.
Larkspur's nightly job re-reads the handbook folder and adds every chunk under a fresh random ID. Each night adds another copy of every chunk. Soon the refund question's top k holds several copies of refund-timing, and the chunk with the other half of the answer no longer fits.
Every LangChain vector store implements the same small interface. The notebook runs one corpus through InMemoryVectorStore, FAISS and Chroma with the same calls:
| Operation | LangChain call | What it does |
|---|---|---|
| Add | add_documents(docs, ids=ids), from_documents(...) |
Embeds the text and stores vector, text and metadata under an ID |
| Read | get(ids=[...]) (Chroma) |
Fetches entries by ID with no similarity search; the first check when retrieval misbehaves |
| Search | similarity_search(query, k=k, filter=...) |
Embeds the query and returns the k nearest entries |
| Delete | delete(ids=[...]) |
Removes entries by ID |
| Update | update_document(document_id=..., document=...) (Chroma) |
Delete, then insert under the same ID |
Table 1: The five index operations, through LangChain's common interface.
No store edits a vector in place. Changing a chunk's text changes its embedding, and the embedding is what the index is built on. An update has to replace the entry. Chroma's update_document deletes the old entry and inserts a new one under the same ID, and the notebook shows the entry count unchanged afterwards:
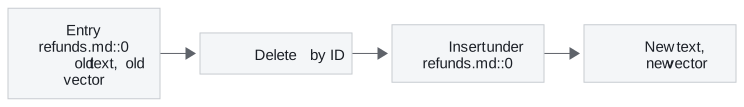
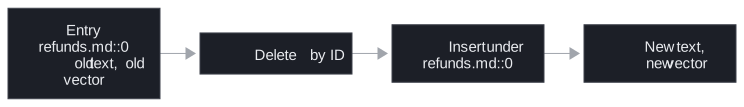
Figure 1: An update replaces the entry under the same ID. The count stays the same.
That only works when you know the ID. Re-adding the same text under a new ID stores it twice: on a six-document Chroma store, adding a document again under its existing ID leaves 6 entries, and adding it under a new ID makes 7. The copy then takes a top-k slot that a different chunk needed. Ingestion pipelines that mint a fresh UUID on every run create a duplicate for every chunk on every run. We call these run-minted IDs, and they are the failure in the opening example.
So derive IDs from the document, never from the run:
f"{source}::{page}::{chunk_index}": readable, and says where the chunk came from.- A hash of the content: re-ingesting unchanged text becomes a no-op. The Indexing API in lesson 5 of T5.5 uses this, with the metadata included in the hash.
- A business key (
ticket_id,article_id) when the source has one.
For Larkspur, refunds.md::0 names the refund-window chunk no matter how often the folder is re-read. When the policy changes, the pipeline can delete or overwrite exactly that entry.
What a score means
similarity_search_with_score returns a number per result, and its meaning depends on the backend:
| Backend | Returned by similarity_search_with_score |
Closer means |
|---|---|---|
| Chroma | Distance in the collection's space; Chroma 1.5.9 defaults to l2 |
Lower |
FAISS (IndexFlatL2) |
Squared L2 distance | Lower |
Pinecone index with metric="cosine" |
Cosine similarity | Higher |
Any store, similarity_search_with_relevance_scores |
A relevance score normalised to 0 to 1 | Higher |
Table 2: What the score means on four backends.
The notebook runs the same query against Chroma and FAISS and gets the same ranking with different numbers. Three rules follow. Never hard-code a threshold without checking what your backend returns, because score > 0.8 can reject everything on a distance scale. We call that a scale-blind threshold. Never compare scores across backends or embedding models. Use scores to rank and to compare results of one query, and set any cut-off from known-good and known-bad queries run on the store you ship.
as_retriever() hides the scores. It wraps the store in the Retriever interface (one method, invoke(query)) so chains can swap backends, and it returns documents only. When retrieval looks wrong, go back to the store and read the scores and the result count.
Persisting and reopening
Chroma with a persist_directory writes as it goes. FAISS is explicit: save_local(dir) writes the index and a pickled docstore, and FAISS.load_local(dir, embeddings, allow_dangerous_deserialization=True) reads them back. The flag exists because unpickling can execute code, so load only indexes you built.
Reopening a store fails silently in two ways:
- Silent empty collection. A wrong collection name does it.
Chroma(collection_name="typo", persist_directory=...)creates a new, empty collection. Its count is 0, every search returns nothing, and no error is raised. - Model swap on reopen. A wrong embedding model does it. The store opens and searches return results, but the query vector and the stored vectors come from different models, so the ranking means nothing.
The notebook turns both into startup errors with an open_store() check: refuse an empty collection, and compare the stored vector's dimension with the live model's. The dimension check misses a model swap with equal dimensions (text-embedding-3-large truncated to 1,536 against text-embedding-3-small), so also store the model name in the collection's metadata and assert it.
In practice: a Larkspur index that survives re-runs
For the handbook store, each rule on this page becomes one decision:
- Derive every ID from the document, such as
refunds.md::0for the refund-window chunk, so a re-read overwrites it. - Update by ID when a policy changes: delete and insert under the same ID.
- Read the scores from the store before setting any threshold, and set it from Larkspur's own known-good and known-bad queries.
- Check at startup that the collection is not empty, that the vector dimension matches the live model, and that the stored model name matches.
Next: lesson 2 of T5.5 opens the index itself: how embedded stores find nearest neighbours without comparing every vector.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| Vector stores and index operations | Open on GitHub | Open in Colab |
| Vector database operations (optional) | Open on GitHub | Open in Colab |
| Other vector stores (optional) | Open on GitHub | Open in Colab |
Key Takeaways
- No store edits a vector in place; an update deletes and re-inserts under the same ID. Derive IDs from the document, such as
source::page::chunk_indexor a content hash, never from the run. - Score meaning depends on the backend: Chroma and FAISS return distances, Pinecone cosine similarity. Set thresholds from known queries on the store you ship.
- Reopening a store with a wrong collection name or embedding model fails silently. Refuse empty collections at startup and assert the stored dimension and model name.
Check yourself
1. Why does an ingestion pipeline that mints a fresh UUID on every run make retrieval worse over time?
Re-adding the same text under a new ID stores it twice: a six-document Chroma store becomes 7 entries. Each copy takes a top-k slot that a different chunk needed, and every run duplicates every chunk again. Derive IDs from the document instead, such as refunds.md::0, a content hash or a business key.
2. Code written for a Pinecone cosine index keeps results scoring above 0.8. You move it to Chroma with default settings. What goes wrong?
Chroma 1.5.9 returns a distance in l2 space by default, where lower is closer, so score > 0.8 keeps the wrong end and can reject everything. Never compare scores across backends or hard-code a threshold without checking what the backend returns. Set any cut-off from known-good and known-bad queries run on the store you ship.
3. After a restart, every search returns nothing and no error is raised. What is the likely cause, and what check turns it into an error?
A wrong collection name: Chroma(collection_name="typo", ...) creates a new, empty collection. The notebook's open_store() check refuses an empty collection and compares the stored vector's dimension with the live model's. Also store the model name in the collection's metadata and assert it, because a swap with equal dimensions passes the dimension check.