Open-source LLMs via Hugging Face Inference and locally
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
Inference endpoints
An inference endpoint is a server that holds a model's weights and answers calls to it. For an open model you choose who runs that server. The notebooks show two of the three options:
| Where the weights run | The call | What you manage | |
|---|---|---|---|
| Vendor API (lesson 1 of T2.2) | The vendor's servers | openai.chat.completions.create(...) |
A key and a budget |
| Hugging Face Inference (02a) | A provider Hugging Face routes to | InferenceClient(...).chat.completions.create(...) |
A token, and which provider serves the model |
| Local (02b) | Your GPU | model.generate(...) or a pipeline |
Memory, the chat template, generation settings |
The 02a notebook calls meta-llama/Llama-3.1-8B-Instruct, an 8B-parameter instruction-tuned model, and deepseek-ai/DeepSeek-V3-0324 with the same messages and max_tokens=1000. The client mirrors the OpenAI call on purpose: client.chat.completions.create(model=..., messages=...) and completion.choices[0].message.content. Code written against the OpenAI shape moves to an open model by changing the client and the model id.
Two details of the hosted path decide what you are actually calling:
- The model id names the weights, not the server. In the installed
huggingface_hub1.16.1, a chat call with noproviderargument defaults to server-side auto routing: Hugging Face picks a provider that hosts the model. Latency and price can differ by provider, so a production client passesprovider=explicitly and records it with each answer. - The notebook's "client without API key" still sends one. It creates
InferenceClient()with no token, after settingHF_TOKENin the environment. Withtoken=Nonethe library falls back toHF_TOKEN, so both of the notebook's clients are authenticated;build_hf_headers(token=None)returns the bearer token from the environment. To send no token at all, passtoken=False.
The notebooks price only the OpenAI models, so this module has no per-answer figure for the open ones. Measure them the same way lesson 4 of T2.2 measures o4-mini: from usage where the provider returns it, or from GPU hours when you host the model.
Running a model locally
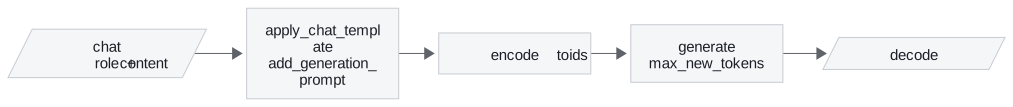
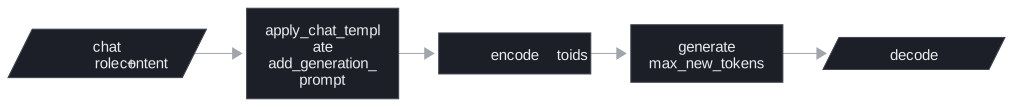
The optional 02b notebook loads google/recurrentgemma-2b-it with transformers in bfloat16 on a CUDA device, and states that it needs at least 5 GB of GPU memory. Running locally exposes the steps a hosted endpoint does for you:
- The chat template. Each chat model was trained on its own markup around roles.
tokenizer.apply_chat_template(chat, tokenize=False, add_generation_prompt=True)writes that markup, and the notebook encodes the result withadd_special_tokens=Falsebecause the template already added them. A hosted endpoint applies the template on the server; locally a wrong template gives fluent but off-format replies. - Generation settings.
max_new_tokenscaps the reply (150 in the first call);max_lengthcaps prompt plus reply, so the notebook uses one or the other.do_sample=Falseis greedy decoding, the same answer every run;do_sample=True, temperature=0.5samples. - What comes back.
model.generatereturns the prompt's token ids followed by the new ones, sotokenizer.decode(outputs[0])prints the template and the question before the answer. Thepipeline("text-generation", ...)call withreturn_full_text=Falsereturns only the new text.
The notebook's markdown calls the model "Google Gemma 2B IT" while the code loads RecurrentGemma, a recurrent variant that the notebook says needs less memory than Gemma on long sequences. The model id in the code is the one that runs.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| Open source LLMs via hugging face inference API | Open on GitHub | Open in Colab |
| Open source LLMs locally (optional) | Open on GitHub | Open in Colab |
Key Takeaways
- For an open model you choose who runs the weights: a routed provider through Hugging Face Inference or your own GPU. The client mirrors the OpenAI call, so moving code means changing the client and the model id.
- The model id names the weights, not the server. Pass
provider=explicitly, record it with each answer, and price open models fromusageor GPU hours. - Running locally means doing the hosted steps yourself: apply the model's chat template, cap the reply with
max_new_tokens, and strip the prompt ids thatgeneratereturns before the answer.
Check yourself
1. Why should a production client pass provider explicitly when it calls an open model through Hugging Face Inference?
The model id names the weights, not the server. With no provider argument, huggingface_hub 1.16.1 uses server-side auto routing and Hugging Face picks a provider that hosts the model, and latency and price can differ by provider. Passing provider= and recording it with each answer tells you what you actually called.
2. You create InferenceClient() with no token to test an unauthenticated call, after the notebook set HF_TOKEN. Is the call unauthenticated?
No. With token=None the library falls back to HF_TOKEN from the environment, so the client sends the bearer token anyway; build_hf_headers(token=None) shows it. Pass token=False to send no token at all.
3. Running RecurrentGemma locally, decoding the first output of model.generate prints the chat template and the question before the answer. Is something wrong?
No. model.generate returns the prompt's token ids followed by the new ones, so decoding the whole output prints both. The pipeline("text-generation", ...) call with return_full_text=False returns only the new text.