HyDE: embed a hypothetical answer
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
HyDE
What you'll learn
- Explain why an invented answer can retrieve better than the question it answers.
- Trace a hypothetical answer through the index, and see a misleading one fail.
- Explain which embedding calls run the LLM and which pass straight through.
- Decide whether HyDE suits a private corpus, with a test rather than an assumption.
Lessons 2 to 4 of T6.2 changed the question's words or its scope. The result was still a question: short, interrogative, unlike the passage that answers it. Lesson 1 of T6.2 called that the shape half of the query–document asymmetry.
HyDE (Hypothetical Document Embeddings, Gao et al., arXiv:2212.10496) attacks the shape. Instead of embedding the question, it asks an LLM to write an answer, embeds that answer, and searches with its vector. An invented answer is declarative, long and full of the vocabulary documentation uses, so it lands nearer the real passage than the question does:
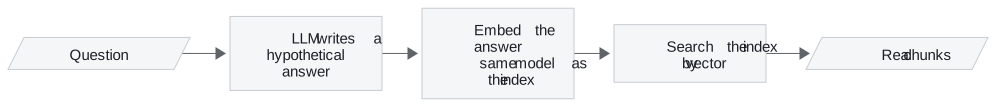
Figure 1: HyDE. The invented answer is a search key; only real chunks come back.
The hypothetical answer may state wrong facts, and that does not matter. It is discarded after embedding, never reaches the user and never enters the context.
Here is the outage question searched three ways on the T5.1 TF-IDF index. The two hypothetical answers are hand-written to show the two outcomes; an LLM would write something similar:
| Search key | Top 3 retrieved | Recall at 2 |
|---|---|---|
| The question: What happens if my server goes down? | reboot 0.416, sizing 0.389, export 0.217 |
0.00 |
| A good guess: "…the uptime guarantee applies. When availability falls below the promised level because of an outage, customers receive service credits, and the status page posts incident updates until recovery." | sla 0.476, incidents 0.423, reboot 0.100 |
1.00 |
| A jargon guess: "…the platform automatically fails over to a standby node in another zone, and live migration restores your virtual machine without data loss." | export 0.511, reboot 0.275, sizing 0.257 |
0.00 |
Table 1: The same question searched by itself and by two hypothetical answers (T5.1 index, TF-IDF; both answers illustrative).
The good guess uses the handbook's words, "availability", "outage", "service credits", "incident", and finds both evidence chunks. The jargon guess describes how a different provider handles failure. Its words ("data", "loss", "zone") pull the search toward the export chunk. We call this invented jargon: a confident hypothetical answer written in vocabulary the corpus never uses.
Two models, one index
HyDE always needs two models: an LLM to write and an embedding model to embed. The embedding model must be the one that built the index, or the vectors are not comparable. The index itself is built plainly. Documents are already answer-shaped, and indexing through an LLM would cost a generation per chunk.
LangChain packages the steps as a hypothetical document embedder, which behaves differently for the two methods every embedding model has:
| Method | Called when | What it does |
|---|---|---|
| Embed documents | Building the index | Passes straight through to the base embedder; no LLM call |
| Embed query | Every search | Runs the LLM, then embeds the generated text |
Table 2: The two embedding paths of the HyDE embedder.
Notebook 05a checks the first row: a document embedded through the HyDE wrapper matches its plain embedding. That pass-through makes the wrapper a drop-in. Hand it to a vector store as its embedding model, and indexing stays plain while every similarity search applies HyDE.
The wrapper ships with built-in prompt templates inherited from the datasets the paper used; the general one asks the model to "write a passage to answer the question". 05a writes its own prompt instead, asking for an excerpt from technical documentation, so the hypothetical answer matches the genre of the indexed chunks.
Several hypothetical answers
The paper generates several hypothetical answers and averages their embeddings, so no single invention dominates the search vector. A jargon guess averaged with two good ones pulls the vector less.
LangChain's current wrapper cannot do this: its chain returns one string, so its averaging step always averages exactly one vector. 05a generates three answers itself at temperature 0.8, embeds them and averages them, then checks how similar the three are to each other. A cosine similarity near 1.0 means the answers are near-identical, and the average bought nothing for three times the generation cost. The optional notebook 05b builds HyDE by hand, then with LangChain's wrapper and a custom prompt; 05c asks for one hypothetical document sized to the index's chunk length, so the search key and the chunks have the same shape.
When it helps and when it hurts
HyDE trades one LLM call for a better-shaped search key:
| Plain retrieval | HyDE | |
|---|---|---|
| Cost per query | One embedding call | One LLM call plus one embedding call |
| Short or vague questions | Often misses | The LLM supplies the missing vocabulary |
| Niche or private corpus | Retrieves what is there | The LLM can invent jargon and steer away from the right chunk |
| Questions that already read like documents | Strong | No better, sometimes worse |
Table 3: Plain retrieval against HyDE.
Pitfall: invented jargon on a private corpus. No model was trained on Larkspur's handbook. Its hypothetical answers come from what it knows about hosting providers in general, and Table 1 shows both outcomes that knowledge can produce.
In practice: testing HyDE on the Larkspur handbook
- Run the golden set twice, with and without HyDE, and count the overlap and the recall per question, as
05aends by doing. - Prompt in the handbook's genre: "Write a short excerpt from a cloud hosting provider's support handbook that answers…"
- Generate three answers and average them when single guesses vary; check their mutual similarity to see whether the extra calls buy anything.
- Route only short, vague questions to HyDE; exact codes go to BM25 (T6.1), compound questions to decomposition.
Lesson 6 of T6.2 takes those compound questions: one query that carries several needs.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| HyDE | Open on GitHub | Open in Colab |
| HyDE walkthrough (optional) | Open on GitHub | Open in Colab |
| HyDE RAG techniques (optional) | Open on GitHub | Open in Colab |
Key Takeaways
- HyDE embeds an LLM-written answer instead of the question, because an answer-shaped text lands nearer the real passage; on the outage question a good guess lifts recall at 2 from 0.00 to 1.00.
- A guess in vocabulary the corpus never uses (invented jargon) misleads the search, and the risk is highest on a private corpus such as Larkspur's.
- Embed with the same model that built the index: the HyDE embedder runs the LLM only for queries. Test on the golden set before turning it on.
Check yourself
1. The hypothetical answer HyDE writes may state wrong facts. Why does that not mislead the user?
It is only a search key. It is embedded, then discarded: it never reaches the user and never enters the context. The chunks that come back from the index are real, and the answer is built from them.
2. Two hypothetical answers to the outage question give recall at 2 of 1.00 and 0.00. What separates them?
Vocabulary. The good guess uses the handbook's words (availability, outage, service credits, incident) and retrieves sla and incidents. The jargon guess describes failover and live migration, words the handbook never uses, and its "data loss" pulls the search to the export chunk.
3. You pass the HyDE embedder to a vector store to build the Larkspur index. Does indexing call the LLM, and what must the base embedder be?
No. Embedding documents passes straight through to the base embedder, so indexing stays plain; only query embedding runs the LLM. The base embedder must be the model that built the index, or the query and chunk vectors are not comparable.