Fusion retrieval with QueryFusionRetriever
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
QueryFusionRetriever
What you'll learn
- Map T6.1's hybrid ensemble onto LlamaIndex's fusion retriever, setting by setting.
- Explain the three defaults that change what a port does.
- Trace a Larkspur question through all four fusion modes, and see which keep the answer.
- Diagnose a fusion retriever fed distances where it expects similarities.
Lesson 1 of T6.6 mapped the pieces. T6.1's hybrid retrieval is where a faithful port most often behaves differently, because the merge has several knobs and LlamaIndex sets them differently.
The query fusion retriever is LlamaIndex's ensemble retriever: it runs several retrievers and merges their lists. Notebook 02a gives it a vector retriever and a BM25 retriever, both returning 2 nodes:
| Setting | 02a's value |
Default |
|---|---|---|
| Retrievers | Vector, BM25 | |
| Retriever weights | 0.6, 0.4 | Equal |
| Number of queries | 1 | 4 |
| Mode | Distance-based score | Simple |
Final similarity_top_k |
Not set | 2 |
Table 1: 02a's fusion settings against the defaults.
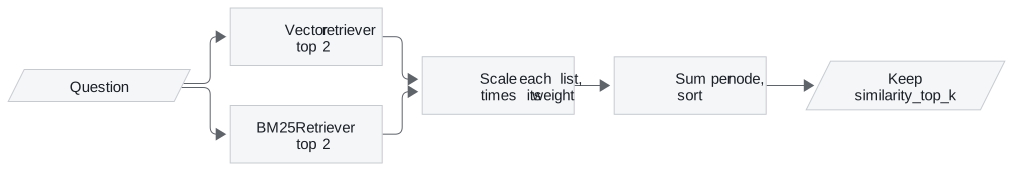
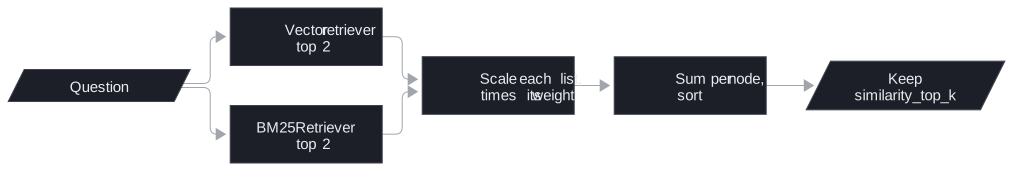
Figure 1: Fusion in 02a.
Three of the defaults change what a port does:
- The number of queries defaults to 4. The retriever keeps your question and asks the configured LLM to write 3 more, then runs every query on every retriever: with two retrievers, 8 retrievals and one LLM call per question.
02asets it to 1, which turns query generation off. T6.2 covers what the extra queries buy. - The final cut defaults to 2.
02adoes not set it, so two retrievers with two hits each still return two nodes. - The mode defaults to simple. The four modes, as the installed
llama-index-core0.14.25 implements them:
| Mode | Scaling inside each list | How lists combine |
|---|---|---|
| Relative score | Min-max: best 1, worst 0 | Times weight, summed per node |
| Distance-based score | Min-max between mean ± 3 standard deviations | Times weight, summed per node |
| Reciprocal rerank | 1 / (60 + rank), rank from 0 |
Summed per node; weights ignored |
| Simple | None | Highest raw score per node |
Table 2: The four fusion modes.
Weights are divided by their sum, so 0.6 and 0.4 stay as they are and 3 and 2 become the same thing. Scores in the two score modes are also divided by the number of queries.
The 45-day question, four ways
On the Larkspur handbook, split into one node per sentence, Can I get a refund on an annual plan after 45 days? gives two short lists. The vector side (all-MiniLM-L6-v2, run locally in place of the notebook's OpenAI model) returns the 30-day rule at 0.6922 and "Monthly plans are not refundable" at 0.5373. BM25 returns the 30-day rule at 2.3898 and the prorated rule, the one that answers the question, at 1.9076. Fused by the real fusion retriever with 02a's settings:
| Mode | Fused top 2 | Prorated rule |
|---|---|---|
| Distance-based score | 30-day rule 0.6667, monthly 0.2000 | 3rd, 0.1333 |
| Relative score | 30-day rule 1.0, monthly 0.0 | 3rd, 0.0 |
| Reciprocal rerank | 30-day rule 0.0333, monthly 0.0164 | 3rd, tied at 0.0164 |
| Simple | 30-day rule 2.3898, prorated 1.9076 | 2nd |
Table 3: Four modes on one question (the real fusion retriever, all-MiniLM-L6-v2 and LlamaIndex's BM25).
Only simple keeps the answer, and for the wrong reason: it compares a BM25 score with a cosine similarity, and BM25 scores run higher. We call that scale collision. Three behaviours explain the rest of the table:
- With two hits per list, the distance-based mode ignores the gap. Two scores have a mean halfway between them and a standard deviation of half their difference, so mean ± 3 standard deviations always maps the better one to 2/3 and the worse to 1/3. In a check with fixed scores, dropping the vector runner-up from 0.80 to 0.10 left every fused score unchanged. The weights then decide the order: 0.6 × 1/3 = 0.2 for the vector runner-up beats 0.4 × 1/3 = 0.1333 for the BM25 runner-up. Flip the weights to 0.4 and 0.6 and the prorated rule takes second place at 0.2.
- Relative score with two hits sends every runner-up to 0. Both second places score 0 here, and the cut falls between equal scores.
- Reciprocal rerank drops the weights. The constant is 60 and ranks start at 0, so a node first in one list scores 1/60. T6.1's ensemble multiplies each term by its weight and counts ranks from 1, so the two "RRF" scores are not interchangeable.
Pitfall: same name, different formula.
02a's note says reciprocal rerank is unsuitable "since there is no normalisation". Rank fusion never looks at the scores, so their scales cannot hurt it; the mode where scales collide is simple, the default. T6.1's fusion lesson works through score and rank fusion in general; in LlamaIndex the same mode names carry different constants.
The BM25 side differs from LangChain's too. LlamaIndex's BM25 retriever uses an English stemmer, English stop words and a word pattern of two or more characters, so "refund" in the question matches "refunds" in the prorated rule. LangChain's splits on whitespace and would not match them: lesson 2 of T6.1's token mismatch, already fixed here.
Score direction
Every fusion mode assumes a higher score is better. 02a's vector retriever comes from the default in-memory store, which returns cosine similarity, so the assumption holds. Wire the notebook's FAISS store in properly (lesson 1 of T6.6) and it stops holding: a flat L2 index returns squared L2 distances as the score, where lower is better.
The same three handbook sentences, retrieved for the 45-day question through two FAISS indexes:
| Sentence | Inner-product index score | L2 index score |
|---|---|---|
| 30-day full-refund rule | 0.6922 | 0.6155 |
| Monthly plans are not refundable | 0.5373 | 0.9254 |
| Prorated rule | 0.5267 | 0.9465 |
Table 4: One ranking, two score directions.
The order is the same; the scale runs the other way. On unit-length vectors the squared distance is 2 minus twice the cosine (2 - 2 × 0.6922 = 0.6156). Feed the L2 list to relative score and the nearest sentence scales to 0 while the farthest gets the full weight. We call this the flipped score, the fusion cousin of lesson 1 of T6.1's flipped threshold.
In practice: Larkspur's hybrid port
- Set every argument: number of queries, final
similarity_top_k, mode and weights; never rely on the defaults. - Retrieve deeper than 2 per list, so min-max modes have more than two points to scale.
- Use reciprocal rerank when the lists' scales differ, knowing it ignores weights.
- Use an inner-product index on normalised vectors for FAISS, and print each retriever's raw scores once before trusting the fused list.
Fusion decides which nodes come back. Lesson 3 of T6.6 reorders and trims them before the model reads them.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| Fusion retrieval with LlamaIndex | Open on GitHub | Open in Colab |
Key Takeaways
- Check the defaults before porting: four queries add an LLM call and multiply retrievals, a final cut of 2 trims the fused list, and the default simple mode compares raw scores across retrievers (scale collision).
- With two hits per list the score modes flatten the gap and the weights decide the order; reciprocal rerank ignores the weights and counts ranks from 0. On the 45-day question three of four modes drop the answer.
- Every fusion mode assumes higher is better. Use inner product on normalised vectors rather than L2 distance (the flipped score), and print each retriever's raw scores once.
Check yourself
1. A port of [T6.1](/learn/retrieval-quality-engineering/retrieval-hybrid-rerank/retrieval-hybrid-rerank-overview)'s hybrid retriever to LlamaIndex sets only the retrievers and weights. What does it do differently from the original?
It generates 3 extra queries with an LLM and runs all four on both retrievers, 8 retrievals per question; it cuts the fused list to 2; and it uses the simple mode, which takes the highest raw score per node and so compares BM25 scores with cosine similarities.
2. In distance-based mode with two hits per list, why does dropping the vector runner-up's score from 0.80 to 0.10 change nothing?
Two scores have a mean halfway between them and a standard deviation of half their difference, so scaling between mean ± 3 standard deviations always maps the better to 2/3 and the worse to 1/3. The gap disappears, and the weights decide the order: 0.6 × 1/3 beats 0.4 × 1/3.
3. A teammate wires FAISS with an L2 index into the fusion retriever in relative-score mode, and the worst sentence starts winning. Why?
The L2 index returns squared distances, where lower is better, but every fusion mode assumes higher is better. Min-max then scales the nearest sentence to 0 and the farthest to 1. Use an inner-product index on normalised vectors, which returns cosine similarity.