Hub setup, datasets and models
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
Hub & cache
The Hugging Face Hub stores models, datasets and Spaces as git repositories named owner/name, such as sentence-transformers/all-MiniLM-L6-v2. Every change to a repo is a commit with a 40-character hash, and branch names such as main point to the latest one. Notebook 01a logs in with notebook_login(), which saves an access token; scripts and servers read the same token from the HF_TOKEN environment variable. Public models download without a token, but gated models need one, and anonymous requests get lower rate limits (the library prints a warning saying so).
The first from_pretrained or pipeline call for a repo downloads its files into a local cache. Every later call reads the files from disk. This is the entry for the embedding model T5.4 and T6.1 use, as it sits in a cache on disk:
~/.cache/huggingface/hub/models--sentence-transformers--all-MiniLM-L6-v2/
├── refs/main                       40 bytes: the commit hash 1110a243…
├── blobs/                          each file once, named by the hash of its content
│   ├── 53aa5117…                   90,868,376 bytes (the weights)
│   ├── cb202bfe…                   466,247 bytes (tokenizer.json)
│   └── …
├── snapshots/1110a243…/            the repo as it was at that commit
│   ├── model.safetensors  -> ../../blobs/53aa5117…
│   ├── tokenizer.json     -> ../../blobs/cb202bfe…
│   └── …                           every file is a symlink into blobs/
└── .no_exist/                      files the library asked for that the repo does not have
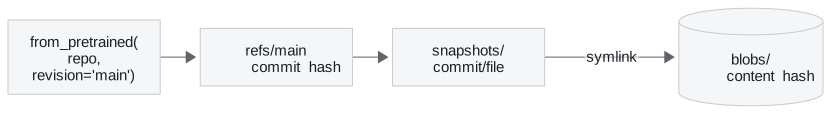
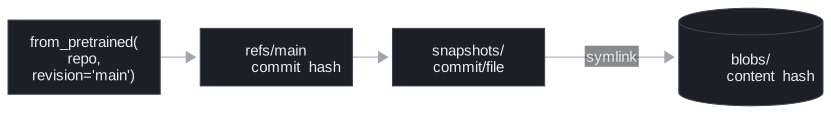
Three consequences follow from that layout:
- A name is not a version.
mainmoves when the owner pushes. Passrevision=with a commit hash to load the same weights in every environment, which is howtransformerspins its own default models (lesson 2 of T2.3). - Revisions share files. Two snapshots of one repo point at the same blob when a file did not change, so a new commit downloads only what changed. Old revisions stay on disk until you remove them.
- The cache is a folder you can move.
HF_HOME(default~/.cache/huggingface) orHF_HUB_CACHE(default$HF_HOME/hub) relocate it, for example to a volume shared by several containers;HF_HUB_OFFLINE=1makes the library read only from it and never call the Hub.
To see what the cache holds, scan_cache_dir() in 01a returns an HFCacheInfo object with every repo, revision and size. The notebook also suggests huggingface-cli scan-cache; in huggingface_hub 1.16.1, the version this course locks, that command prints "huggingface-cli is deprecated and no longer works". Use hf cache ls to list repos and sizes, hf cache rm to delete one, and hf cache prune to remove revisions no branch points to.
Datasets use the same Hub and their own cache. Notebook 01b calls load_dataset('rotten_tomatoes', cache_dir='rotten_tomatoes_data'); the relative cache_dir writes a data folder next to the notebook instead of into the shared cache. The dataset has three splits (8,530 training, 1,066 validation and 1,066 test reviews), and the notebook divides its correct predictions by a hard-coded 1066. Write len(test_df) instead, so the accuracy stays right if the split changes. The Hub now lists the dataset as cornell-movie-review-data/rotten_tomatoes; if the short name stops resolving, use the full id.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| HF setup | Open on GitHub | Open in Colab |
| HF basics | Open on GitHub | Open in Colab |
Key Takeaways
- Hub repos are git repositories, and a branch such as
mainmoves when the owner pushes. Pinrevision=to a commit hash to load the same weights in every environment. - The cache stores each file once as a content-hashed blob and links snapshots to it, so a new commit downloads only what changed. Clear old revisions with
hf cache prune. - Relocate the cache with
HF_HOMEorHF_HUB_CACHEand setHF_HUB_OFFLINE=1on servers that must never call the Hub. Compute accuracy fromlen(test_df), never a hard-coded count.
Check yourself
1. Why does loading a model with revision main not guarantee the same weights in every environment?
A name is not a version. main is a branch that moves when the owner pushes, and refs/main holds whichever commit hash it points to now. Pass revision= with a commit hash to load the same weights everywhere, which is how transformers pins its own default models.
2. The owner of all-MiniLM-L6-v2 pushes a commit that changes only tokenizer.json. What does your next load of main download, and what stays on disk?
Only the new tokenizer.json. The new snapshot's model.safetensors symlink points at the same 90,868,376-byte blob, because that file did not change. The old revision stays on disk until you remove it; hf cache prune removes revisions no branch points to.
3. Several containers share one model cache, and the servers must never call the Hub. Which settings do you use?
Point HF_HOME or HF_HUB_CACHE at the shared volume, and set HF_HUB_OFFLINE=1 so the library reads only from the cache. Pin each model with revision= and a commit hash so every container loads the same snapshot.