Evaluator–optimiser loops, always bounded: LangGraph vs LCEL
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
Bounded loops
What you'll learn
- Explain how an evaluator-optimizer loop feeds a critique back into the next draft.
- Design criteria an evaluator can pass, with the verdict computed in code.
- Prove that a loop ends when the evaluator never approves, and count its worst-case calls.
- Choose where the loop lives: LangGraph, a Python loop around LCEL, or agent middleware.
Lessons 1 to 4 of T7.3 all run forward: every step happens once, or a fixed number of times. The 24.1 gate could retry, but it only re-ran extraction blind. This lesson's pattern sends the reason for a rejection back to the step that can fix it.
A Larkspur answer can cite the handbook and still promise a refund the policy does not allow. A reviewer that names that problem, and a generator that revises with the review in hand, can catch it. The risk is a reviewer that never says yes.
Generate, evaluate, revise
Evaluator-optimizer generates a draft, grades it against explicit criteria and feeds the critique into the next draft, until the grade passes or a cap is reached. The 24.1 gate decided whether a result may proceed; this loop sends feedback to the generator. It pays off when two things hold: the criteria are clear, and feedback measurably improves the next attempt.
The lesson's loop writes a short joke about agentic AI:
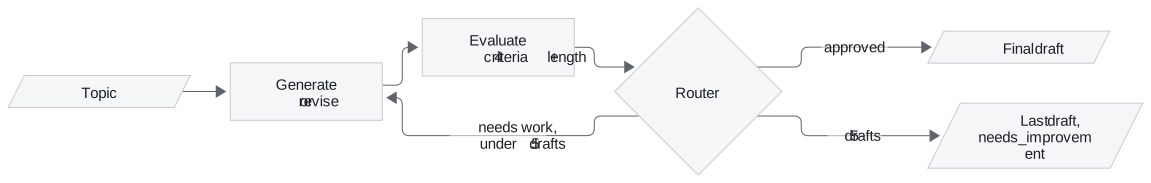
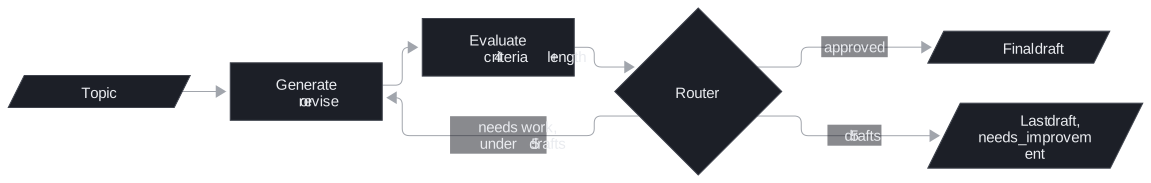
Figure 1: The bounded loop. Approval ends it, and so does the fifth draft.
The generator runs at temperature 0.7, so a revision can differ from the draft before it. The evaluator runs at 0 to keep grading as consistent as possible, though the same draft can still get a different grade on another call. From the second pass on, the generator receives the previous draft and the feedback, so it revises instead of starting over.
Criteria an evaluator can pass
The evaluator is only as useful as its criteria. A first version of the notebook asked for one holistic grade against loose criteria such as "is it genuinely funny?", and with gpt-4o-mini the loop almost never converged: the evaluator kept finding something that could be better. We call this the moving bar. The bounded version changes three things:
| Change | In the reference loop | Why |
|---|---|---|
| One yes-or-no per criterion | clear punchline; a punchline that depends on agentic AI specifically; no stock template; appropriate | A met criterion passes even when the joke could be better |
| Code checks what code can check | Length is a word count of at most 40, computed in code | A model should not be asked to count |
| The verdict is computed | approved only when every criterion and the length check pass; otherwise needs improvement, with one fix named per failed criterion | The model never asserts the grade itself |
Table 1: From a holistic grade to computed criteria.
Proving the loop stops
A structured verdict does not guarantee the evaluator will ever approve. So the router checks two things in order: approval first, then the iteration count against a cap of 5. We ran the reference stopping rule on four states:
| Grade | Iteration | Router returns | What happens |
|---|---|---|---|
| needs improvement | 1 | refine | the generator revises with the feedback |
| needs improvement | 5 | cap reached | the run ends with the last draft, marked needs improvement |
| approved | 5 | approved | the run ends with the draft |
| approved | 2 | approved | the run ends early |
Table 2: The router's decisions. Approval is checked first, and no state starts a sixth draft.
The notebook proves the cap on a live generator with a stub reviewer that rejects every draft and makes no LLM call. Without the cap branch, that cell would never finish. With it, the run ends after five drafts.
The cap also bounds cost. Each pass is one generator call and one evaluator call:
| Outcome | Passes | LLM calls |
|---|---|---|
| Approved on the first draft | 1 | 2 |
| Approved on the third draft | 3 | 6 |
| Never approved | 5 | 10, the worst case |
Table 3: Calls per run under a cap of 5.
Planted failures
Each guard has a case that shows why it is there:
| Planted failure | What happens | The guard |
|---|---|---|
| The moving bar: one holistic grade | The loop almost never converges | Yes-or-no criteria, verdict computed in code |
| A reviewer that rejects everything | Without a cap, the loop never ends | The router's iteration cap |
| A model asked to count words | Length checks drift | A word count in code |
| A cap set only by the framework | The pinned LangGraph's default recursion limit is 10,007 steps, about 5,000 passes | The cap in the router; an explicit recursion limit as a second net, as 24.1 sets |
Table 4: One planted case per guard.
Pitfall: the capped success. A run that ends at the cap returns a draft that did not pass. Count it as a failure, and watch the share of runs that end there: it rises when criteria drift or a new evaluator model is stricter than the old one.
Where the bound lives
The bound sits in a different place in each implementation:
| Implementation | The loop is | The bound is |
|---|---|---|
| LangGraph | a conditional edge back to the generator | the iteration cap checked in the router |
| LCEL plus Python | a for loop around two chains |
the loop's range, 1 to the cap |
| Agent middleware | a hook after each model call that jumps back to the model | a model-call limit of 5 that ends the run |
Table 5: Three homes for the same bound.
For Larkspur, an answer-quality check is the natural evaluator, written as yes-or-no criteria: does the reply cite a handbook chunk, does it state the refund window the chunk states, does it avoid promising anything the handbook does not say, and is it under a length limit counted in code. CRAG (T9.2) applies the same loop to retrieval: grade the documents, rewrite the query, try again, within a bound.
Where LCEL stops
LCEL, the LangChain Expression Language, composes runnable steps into a flow. Every earlier T7.3 pattern is a flow without cycles, so each maps onto an LCEL building block. This one has a cycle, and LCEL has no block for "go back and try again until a check passes":
| Pattern | LangChain 1.x building block | Full coverage |
|---|---|---|
| Prompt chaining | the pipe, plus retry and fallback wrappers | yes |
| Routing | a branch runnable | yes |
| Parallelization | a parallel runnable | yes |
| Orchestrator-worker | mapping a runnable over a list | the fan-out; shared state and per-worker durability need Send |
| Evaluator-optimizer | a Python loop, or a middleware hook that jumps back to the model | yes, outside LCEL itself |
Table 6: The five patterns and their LCEL coverage.
Two tempting shortcuts fail:
- Piping generator, evaluator, generator builds a three-step chain that runs the generator twice. It never loops.
- A retry wrapper re-runs a step blind, with no memory of why the last attempt failed. Feeding the critique forward is the point of the pattern.
Choosing the runtime around the loop
The two LangChain loops differ in what surrounds them:
| Python loop around LCEL | Agent middleware | |
|---|---|---|
| Reads as | a plain for loop |
one agent run with every pass nested |
| State | a dict you shape | the full message history |
| Tracing | each pass as separate chain runs | one run |
| Streaming, persistence | none | inherited from the agent runtime |
| How the critique arrives | passed into the next prompt | appended to the conversation as a user message |
Table 7: Two ways to loop without LangGraph.
In the middleware version the hook must declare that it may jump back to the model; that declaration is what creates the conditional edge. When the loop needs checkpoints, interrupts or a human in it, move it to LangGraph.
Limits of this evidence
- No recorded convergence counts. The notebooks ship without outputs, so how many passes a real joke needed is not measured here; the "almost never converged" result is the notebook's own report on its first version.
- Model-free router trace. Table 2 runs the reference stopping rule on hand-set states, not a live loop.
- One task. Jokes are a cheap stand-in; Larkspur criteria were not run.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| Evaluator optimiser LangGraph | Open on GitHub | Open in Colab |
| Evaluator optimiser lcel | Open on GitHub | Open in Colab |
Key Takeaways
- Evaluator-optimizer feeds a critique into the next draft until the grade passes. Use it only when the criteria are clear and feedback measurably improves the next attempt.
- Grade with one yes-or-no per criterion, check length in code and compute the verdict from the checks. A single holistic grade becomes a moving bar the loop rarely clears.
- Cap every loop in your own code, count a run that hits the cap as a failure, and do not rely on the framework's default limit. LCEL cannot express the cycle, so use a Python loop or middleware, and LangGraph when you need checkpoints or interrupts.
Check yourself
1. Why did replacing one holistic grade with one yes-or-no per criterion make the joke loop converge?
Against a loose holistic grade the evaluator kept finding something that could be better, a moving bar. With yes-or-no criteria, a met criterion passes even if the joke could improve, length is counted in code, and approval is computed only when every check passes, so the model never asserts the grade itself.
2. With a cap of 5 iterations, how many LLM calls can one run make at most, and how should you count a run that hits the cap?
Ten, because each pass makes one generator call and one evaluator call. A run that ends at the cap returns its last draft marked needs improvement, so count it as a failure and watch the share of runs that end there.
3. A teammate builds the loop in LCEL by piping generator, evaluator and generator again, or by adding a retry. Why does neither work?
Piping builds a three-step chain that runs the generator twice; it never loops. A retry re-runs a step blind, with no memory of why the last attempt failed, while feeding the critique forward is the point of the pattern. Use a Python loop or a middleware hook that jumps back to the model, and move to LangGraph when the loop needs checkpoints or interrupts.