Retrieval with a user-feedback loop
- Source
- From the RAG & Agents Engineering course
- By
- Sourav Banerjee
- Last updated
- 9 Nov 2026
The feedback re-ranker
What you'll learn
- Explain how an average rating becomes a score multiplier, and why it stays between 1/3 and 5/3.
- Trace one thumbs-down that fixes a question, and one that changes nothing.
- Compare a rating on the whole answer with a signal on each source.
- Diagnose what goes wrong when highly rated answers are folded back into the index.
Lesson 1 of T9.5 checked one answer at a time and could only remove. This lesson learns across many answers.
A Larkspur customer asks How long does a refund take? and gives the answer a thumbs-down. Twenty askings later the answer is still incomplete, because the chunk with the answer, refund-timing, was never among the candidates the ratings could touch.
The feedback record and the multiplier
The notebook builds a question-answering chain with gpt-4o over a climate-change PDF and stores one feedback record per answer, appended to a log file as a line of JSON:
| Field | What it holds |
|---|---|
query |
The question asked |
response |
The answer given |
relevance |
The user's 1 to 5 rating of how relevant the answer was |
quality |
The user's 1 to 5 rating of its quality |
comments |
Free text, often empty |
Table 1: One feedback record.
On the next query a feedback re-ranker re-weights the retrieved chunks. For each chunk and each stored record, it asks gpt-4o whether that record is relevant to the current query and that chunk. It averages the relevance of the records judged relevant, multiplies the chunk's score by that average divided by 3 (3 is the neutral middle of the scale), and sorts by the new score:
- Event 4 asks “Is there a credit if my server plan has an outage?” Its evidence is the sla chunk.
- TF-IDF returns sizing, reboot, sla and export. With no ratings yet, every relevance_score is 1.000 and the retriever’s order stands.
- The answer uses the top two, sizing and reboot. The evidence is third, so recall@2 is 0.00.
- The user gives a thumbs-down, a rating of 1.
- Both chunks in the answer drop to 1/3, or 0.333. sla and export move up at 1.000.
- Event 9 asks the same question, and the answer now uses sla and export.
- The answer holds the evidence, so the user gives a thumbs-up, a rating of 5.
- sla and export rise to 5/3, or 1.667. Recall@2 has gone from 0.00 to 1.00, and the 91 events after this change nothing.
Figure 1: The feedback loop. Ratings re-weight the next retrieval's candidates; they never change which candidates come back.
Four properties of the rule
The arithmetic is short:
| Average rating | Multiplier | Chunk score |
|---|---|---|
| 1 (every rating a thumbs-down) | 1/3 | 0.333 |
| 3 (neutral) | 1 | 1.000 |
| 5 (every rating a thumbs-up) | 5/3 | 1.667 |
Table 2: The multiplier at the ends and the middle of the scale.
- Feedback sets the order on its own. Every chunk starts at a score of 1.0, so after the multiplication ratings alone decide the order. Similarity only breaks ties, because a stable sort keeps the retriever's order for equal scores.
- The multiplier is bounded. It uses the average, so a chunk sits between 0.333 and 1.667. The first rating moves a chunk as far as it will go; later ratings only move the average.
- It reorders the candidates and nothing else. The retriever returns 4 chunks by default, and a chunk outside those 4 never receives a rating: the candidate ceiling from lesson 1 of T9.5 again.
- It costs one model call per pair. Every retrieved chunk is checked against every stored record, so 4 chunks and 1,000 records make 4,000
gpt-4ocalls for one query.
One hundred ratings on the handbook
The interactive lab runs this rule on the Larkspur handbook with the T5.1 TF-IDF retriever. Five golden questions take turns, 20 times each over 100 events. Each answer uses the top 2 of the 4 candidates, and the simulated user gives a 5 when every evidence chunk is in the answer and a 1 otherwise. The lab replaces the gpt-4o relevance call with a fixed rule: a record counts for a chunk when it was given on the same question and its answer used that chunk. Its port of the rule matches the Python function on all 202 settings it offers.
| Golden question | Recall@2 before | After 100 events | Wrong answers |
|---|---|---|---|
| Can I export my data after I cancel my plan? | 1.00 | 1.00 | 0 |
| How long does a refund take? | 0.50 | 0.50 | 20 |
| What happens if my server goes down? | 0.00 | 0.00 | 20 |
| Is there a credit if my server plan has an outage? | 0.00 | 1.00 | 1 |
| Can I still use my server after I cancel the plan? | 1.00 | 1.00 | 0 |
| Mean recall@2, and total wrong answers | 0.50 | 0.70 | 41 |
Table 3: The lab after 100 rated answers, ratings on the whole answer.
Three results stand out:
- The credit question is fixed by one rating. Its candidates arrive as
sizing,reboot,sla,export. At event 4 the answer usessizingandreboot, the user gives a 1, and both drop to 0.333.slaandexportmove up at 1.000, the next answer contains the evidence, and the thumbs-up at event 9 lifts them to 1.667. - The loop stops learning early. No ranking changes after event 8 and no score changes after event 9. Events 10 to 100 add records and change nothing.
- Feedback cannot reach a missing chunk.
refund-timingscores 0 for the refund question, andslaandincidentsscore 0 for the outage question, so none of them is ever a candidate. Those two questions account for 40 of the 41 wrong answers. On the outage question, every candidate has an average of 1 by event 8, all sit at 0.333, and the order is the retriever's again.
Three defects to fix before the loop works
The notebook's loop does not yet behave as described. Each defect fails quietly:
| Defect | What happens | Fix |
|---|---|---|
| The relevance check compares the model's reply with lowercase "yes", while the prompt asks for "Yes" or "No" | No record ever counts, so no score moves | Normalise case and whitespace before comparing |
| The vector store returns its stored chunk objects, and the score is multiplied in place | The adjustment persists and compounds: one rating of 5 gives 1.667 on the first query and 2.778 on the second | Adjust copies of the chunks |
| The re-ranked list is handed to the retriever as a search setting it ignores | The retriever searches the index again, and the re-ranked order is lost | Pass the re-ranked chunks to the answer step directly |
Table 4: Three defects in the notebook's feedback loop.
All three leave the pipeline answering, so test the order itself.
Implicit vs explicit feedback
Explicit feedback is a judgement the user states: a thumbs-up, a star rating, the 1 to 5 relevance and quality fields above. Implicit feedback is inferred from what the user does next. The two differ on every axis that matters:
| Explicit | Implicit | |
|---|---|---|
| Examples | Thumbs up or down, a 1 to 5 rating, a comment | Opening a cited source, copying the answer, asking the same question again in other words, opening a support ticket |
| Meaning | Clear: the user said it | Inferred: a rephrased question probably means the answer missed |
| Volume | Only from users who choose to rate | From every session |
| What it rates | The whole answer | Often one source, such as the one the user opened |
| Bias | Raters choose themselves, so they may not be typical users | Users click what is shown first, so top-ranked chunks collect more signal |
Table 5: Explicit and implicit feedback compared.
Where the rating lands
The lab's second setting shows why granularity matters. Thumbs on the answer gives every chunk in the answer the same rating, as the notebook does. Clicks on each source rates each chunk on its own: 5 for an evidence chunk the user opened, 1 for one they skipped.
Answer-level ratings produce ride-along credit: a chunk that happens to sit next to the evidence collects the evidence's rating. It works in both directions, as the lab shows after 100 events:
| Question | Chunk | Evidence? | Thumbs on the answer | Clicks on each source |
|---|---|---|---|---|
| Can I still use my server after I cancel the plan? | sizing |
No | 1.667 | 0.333 |
| Can I still use my server after I cancel the plan? | cancel |
Yes | 1.667 | 1.667 |
| How long does a refund take? | refund-window |
Yes | 0.333 | 1.667 |
| How long does a refund take? | reboot |
No | 0.333 | 0.333 |
Table 6: Chunk scores after 100 events under each signal.
On the cancel question sizing rides up next to cancel. On the refund question the answer is always incomplete, so the evidence chunk refund-window is pushed down with the distractor it was served with.
The sharper signal does not change the lab's totals: with either setting, mean recall@2 ends at 0.70 and 41 of 100 answers are wrong, because neither reaches a chunk the retriever does not return. Per-source ratings reshuffle non-evidence chunks for longer, and the order settles at event 15 instead of event 8.
Interview tip: Collect both signals. Implicit ones give volume and per-source detail once corrected for position (compare clicks at the same rank, or occasionally shuffle the sources). Explicit ratings are fewer but mean what they say, and every thumbs-down is a golden-set candidate.
Re-ranking leaves the index alone. The notebook's second half changes the index itself.
Folding good answers into the index
The notebook's second use of feedback is a periodic job, run "daily or weekly". It keeps the records rated 4 or more on both relevance and quality, joins each question and answer into one text, appends that text to the original document, and re-encodes everything (1,000-character chunks, 200 overlap) into a new vector store.
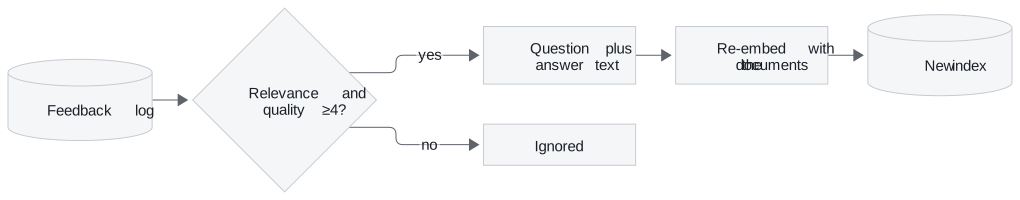
Figure 2: The fold-back job. Only answers that were already good enter the new index.
This adds chunks worded the way users ask, which helps questions phrased like past ones. It has three limits:
- Only answers that were already good get in. In the lab, the refund and outage questions never earn a thumbs-up, so nothing about them would be added. The questions that most need new text get none.
- Past answers become retrievable facts. When Larkspur changes its refund rule, the stored answers still quote the old one, and they match refund questions better than the handbook because they were written as answers to them. We call this stale-answer echo. Tag each added chunk with its date and the handbook chunks it came from, drop it when those change, and rank feedback chunks below primary documents.
- It rebuilds the whole index. Every run re-embeds the full corpus plus the feedback text. Incremental upserts (T5.5) avoid that.
Run the notebooks
The code for this lesson is in these notebooks. Colab runs one in your browser: install the packages its first cell imports and set the API keys it reads. To run every notebook as written, clone the repository and use its uv environment.
| Notebook | GitHub | Colab |
|---|---|---|
| Retrieval with feedback loop | Open on GitHub | Open in Colab |
Key Takeaways
- The feedback re-ranker multiplies each chunk's score by its average rating over 3, so a chunk stays between 0.333 and 1.667 and ratings alone set the order. It costs one model call per chunk and stored record.
- Feedback only reorders the candidates retrieval returns. In the lab, mean recall@2 rose from 0.50 to 0.70, but 40 of the 41 wrong answers came from chunks that were never candidates.
- Combine implicit and explicit feedback, and rate sources rather than whole answers where you can, so credit does not ride along to the chunk beside the evidence. Each thumbs-down is a golden-set candidate.
Check yourself
1. Why can the feedback re-ranker never fix the refund and outage questions in the lab?
It only reorders the 4 candidates the retriever returns. refund-timing, sla and incidents score 0 for those questions, so they are never candidates and never receive a rating. The two questions account for 40 of the 41 wrong answers.
2. For the question about using a server after cancelling, how do thumbs on the answer and clicks on each source treat the sizing chunk?
sizing is not evidence but sits in every good answer next to cancel. Rated through the answer it rides along to 1.667; rated per source it falls to 0.333. Either way the lab's totals stay at mean recall@2 0.70 and 41 wrong answers, because neither signal reaches a chunk the retriever does not return.
3. You plan to fold highly rated answers back into the index every week. What happens when Larkspur changes a policy, and how do you guard against it?
The stored answers still quote the old policy and compete with the corrected handbook as retrievable facts, often winning because they were written as answers to those questions. Tag each added chunk with its date and the handbook chunks it was answered from, and drop it when those change.