Interview Guide · 13 min — Start here. The answer you would talk through in the interview, readable on its own.
Sales process is the path from “we might sell” to “the deal is won or lost”: find a company, book a meeting, learn their pain, send a proposal, negotiate, update CRM (customer relationship management), close.
G05 covers one slice of that loop: prep for a meeting, then maybe a follow-up and a CRM update. Not the whole funnel.
End to end, as Sara:
- Calendar says Acme tomorrow. Overnight we pack her Acme brief (only what she is allowed to see).
- She opens the copilot and asks: summary, risks, discovery questions, draft email, suggested CRM fields.
- We check who she is, pick a path (cached brief, a number lookup, search in notes, or a short agent), and fetch allowed evidence.
- We check permissions again, then the model writes from that evidence.
- If she wants an email or a discount claim, we block anything not on the approved sheet.
- If she wants CRM changed, she previews the exact fields, clicks yes, we write once.
That’s it: prepare → ask → prove it from her data → don’t invent claims → don’t write CRM until she says yes. Prospecting, legal, and billing stay out of scope.
Core idea: Give a rep a useful, cited account brief without showing records they cannot access, inventing customer facts, making unapproved claims, or writing to CRM without preview and approval.
Use this for the spoken design. The Deep Dive has the mechanisms and incident drill, and the unchanged source case is the full reference.
1. Start with the workflow and risk boundary
An account executive has a meeting soon. They need an account summary, opportunity risks, discovery questions, email drafts, and CRM update suggestions. These outputs sit on three levels of risk: read-only assistance, drafts the rep reviews, and approved write-back. A ten-minute saving is worthless if the draft invents a certification or the rep sees a peer’s territory.
“I’ll start from the pre-meeting workflow and separate reading, drafting, and writing. I’ll make the brief fast by precomputing it as the rep, then recheck their permissions at serve time. Any customer-facing claim must be approved and cited; any CRM write must be previewed and approved.”
Questions to ask the interviewer
The source discovery, §1 expands these questions:
| Question to ask | What it's really asking | What you then decide |
|---|---|---|
| Which sales task is slow or inconsistent, and what decision follows the brief? | Is this "prep me for the Acme call in 20 minutes," and does the brief change what they say on the call? | First workflow, the five outputs, and the success metric. |
| Who uses, reviews, and owns a wrong answer or outbound claim? | If the email claims a certification we don't have, who gets blamed — the rep, sales ops, or legal? | Who approves, who audits, and who we escalate to. |
| Which tasks are read-only, draft-only, or require approved write-back? | Can it show CRM facts, only draft an email, or actually update the opportunity after a click? | Tool allowlist and what v1 may write. |
| Which systems are authoritative, fresh, and permissioned by account/territory? | Can a rep see a peer's deal in another territory, and is last quarter's usage still "current"? | Connectors, structured vs semantic route, and snapshot freshness. |
| Which claims, prices, discounts, or customer references are approved externally? | Can the draft promise 20% off, or only prices from the approved sheet? | Claim verifier and which pricing policy version is live. |
| What must be refused when evidence or access is missing? | If we don't have the contract, do we invent a renewal date or say we don't know? | Abstain, mark stale, or fall back. |
| What should a 30-day pilot prove? | After a month, did prep get faster without fake claims going out? | Accuracy, prep time, adoption, claim safety, and outcomes. |
| What must an audit reconstruct? | If legal asks why that email mentioned HIPAA, can we show the source, the permission check, and who approved send? | Evidence IDs, versions, permission checks, draft approval, and write receipt. |
If these answers are missing, keep the first release read-only, restrict sources to approved accounts, and treat external drafts and CRM writes as gated.
The anchor for its sales-assistant variants
| Related case | What changes from G05 |
|---|---|
| Account-research assistant question | Broader CRM/email/usage/support/public-source integration, entity resolution, seller adoption and time saved. |
| Slow agentic CRM assistant | Serial tool calls and agent steps likely dominate (confirm in traces); precompute, cache, parallelise reads, and bound the graph. |
| Sales email model-regression incident | Claim-level release gates, online unsupported-claim monitoring, and block-mode policy enforcement dominate. |
2. Requirements: Functional + Non-Functional
The easiest way to frame requirements in an interview is:
Functional = what the system does. Non-functional = how well it does it and what constraints it must satisfy.
Functional requirements — what the system must do
- Produce the five workflow outputs — each with its own risk level.
- Ingest approved sources — CRM, transcripts, email/calendar, product, pricing, support, warehouse, with IDs, freshness, and ACL (access control list) metadata.
- Filter by permission — tenant, role, territory, sharing, field access; recheck before generation or serving.
- Cite account facts and risks — from fetched records; expose missing evidence.
- Verify outbound claims — approved messaging and versioned pricing policy.
- Preview CRM field changes — require approval before write-back.
Non-functional requirements — how well / under what constraints
| Requirement | Example target / constraint |
|---|---|
| Latency | In this design, interactive answers around 3–8 s; pre-meeting brief built ahead of time; long work async. |
| Availability | During selling hours, serve a permitted last snapshot with a staleness label when safe, or refuse. |
| Security | SSO, CRM record/field permissions, tenant/region constraints, scoped secrets; no customer-data training without contract permission. |
| Correctness | Unsupported external claims blocked; missing citations or uncertain access fail closed. |
| Audit | Queries, evidence, permissions, model/policy version, draft approvals, final output, write receipt. |
| Cost | Budget per workflow; cache stable sources; prune retrieval; small models for routing, stronger model only when justified. |
First release
Exclude autonomous email sending, unapproved CRM writes, disallowed price/discount quotes, lead scoring, out-of-territory access, and independent long-term customer memory.
Interview shortcut
If asked “What are the requirements?”, say:
“Functionally, I prep a permission-scoped brief, cite facts, block unapproved claims, and preview CRM writes. Non-functionally, 3–8 second asks, recheck access at serve time, and never let a snapshot outlive a territory change.”
3. Architecture
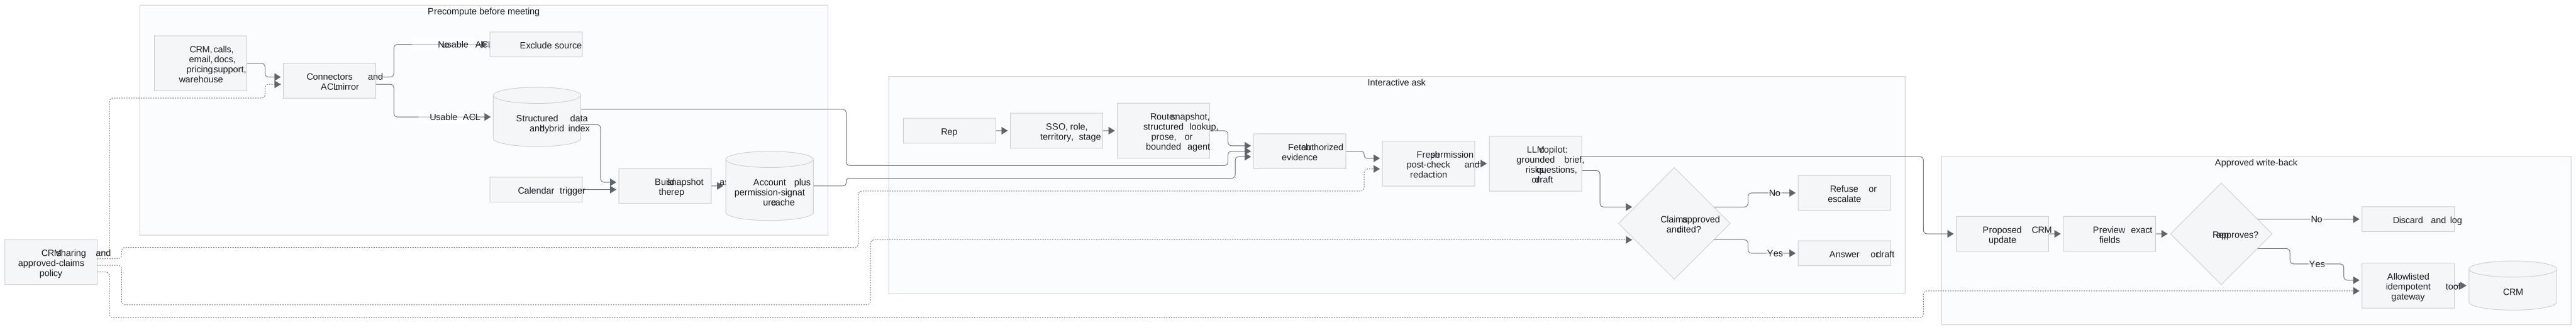
This condenses the source architecture, §4 into three lanes.
Step-by-step architecture
- Step 1. Prepare authorised data. Connect CRM and other sources, mirror their ACLs, and exclude records whose permissions cannot be represented.
- Step 2. Precompute a rep-scoped snapshot. Keep structured facts and searchable prose; a calendar trigger builds a meeting snapshot as the rep and caches it with a permission signature.
- Step 3. Resolve the current rep context. At question time, check SSO identity, role, territory, and deal stage.
- Step 4. Route and fetch. Use deterministic snapshot, structured lookup, or prose routes for common asks; reserve a bounded agent path for ambiguous multi-step asks.
- Step 5. Recheck access. Apply fresh permission checks and field redaction before using cached or live evidence; a snapshot never grants access.
- Step 6. Ground and verify. The LLM (large language model) copilot builds the brief, risks, questions, or draft from authorised evidence; verify citations and approved claims, or refuse and escalate.
- Step 7. Control CRM write-back. Preview exact proposed fields, require the rep's approval, and send approved updates through the allowlisted idempotent gateway; discard and log rejected changes.
Model and agent role: The LLM copilot summarises and drafts from permission-checked evidence. A bounded agent can coordinate ambiguous next steps, but common CRM counts and lookups stay on reviewed deterministic routes. The model cannot approve an external claim or write to CRM.
Three boundaries: precompute keeps slow source fan-out off the question path; the permission post-check protects a snapshot after a territory change; preview and approval protect every CRM write. Precomputation speeds access but never grants access.
5. Route questions to the right evidence
Use semantic/hybrid search for “summarise the last three calls,” a fixed structured CRM operation for “how many open opportunities missed the close date?”, and direct ID lookup for a named opportunity. Mixed questions filter CRM records first, then summarise related prose. A vector search cannot compute an authoritative count; a generated database query may invent fields or scan outside the rep’s scope. Use reviewed operations behind the same allowlist as tool calls.
Opportunity risks come from fetched fields: old stage, slipped close date, competitor mention, unanswered follow-up, open escalation, and relevant playbook objection. Cite each. If fields are absent or transcripts stale, say what could not be checked; do not infer what a typical deal “probably” looks like.
6. Claims and write-back
Every external email claim must map to an approved-claims playbook entry or current pricing policy. The verifier blocks, rather than merely warns, on unsupported or internal-only claims. Personalization uses the account’s own record and interactions. A draft remains the rep’s to review and send; the assistant does not send email in the first release.
A CRM update is a proposal: exact fields previewed → policy check → human approval → idempotent gateway → CRM receipt/audit. Read tools may run automatically. Amount, stage, close, and externally visible actions remain above the risk threshold on day one; only proven low-risk fields might later earn auto-approval.
7. Failure, latency, and cost
| Failure | Safe response |
|---|---|
| CRM down | Last authorised snapshot with staleness label where safe; no writes. |
| Permission or approval service down | Fail closed; no answer from uncertain access and no write. |
| Missing/stale evidence | Disclose gap, abstain or escalate; never fill from model memory. |
| Unapproved price/certification/ROI claim | Block external draft. |
| Prompt injection in transcript/email | Untrusted data; tools and claim policy are gated outside the model. |
| Model or vector path down | Narrow labelled fallback or queue with progress. |
At 10× accounts, shard snapshot jobs by territory and isolate connectors by source. If account prep takes 30–45 s, trace steps and tool latency first. Precompute on the calendar event; use deterministic routes, cache the permission-scoped snapshot, parallelise remaining read-only calls, cap steps/top-k, and reserve an agent for ambiguous work. Measure cache hit rate, p95, steps, tool time, and cost per workflow.
8. Evaluation, rollout, and regression drill
Gate on zero permission violations and zero critical unsupported external claims. The source’s example thresholds also include ≥90% grounded claims, ≥95% correct citations, ≥80% target workflow completion, and ≥95% correct high-risk escalation. Report prep-time reduction, adoption, brief accuracy, citation coverage, conversion/meeting quality, latency, and cost alongside safety. Critical slices pass independently; an aggregate score cannot hide them.
Start with one CRM connector, three reps in distinct territories, historical briefs and SME-approved answers. Add permission red-team and claim-level negative cases, shadow mode, live read-only pilot, then drafts and approved write-back. Keep model versions pinned and canary each route change.
The source regression, §14 shows why: a model upgrade had a 96.7% aggregate pass rate over 120 cases, but only six regulated-claim cases passed at 83.3%; online unsupported claims rose from 1.2% to 8.7%, and the verifier had been changed to warn-only. Contain by rolling back the model route and restoring block mode. Add independent gates for pending certifications, internal-only ROI (return on investment), and unapproved customer references.
9. Interview delivery
Spend the hour on workflow and risk (8 min), sources/permissions (7), architecture (10), CRM and evidence/claim boundaries (15), failure/evaluation/rollout (10), close and follow-ups (10).
“I’d design around the rep’s pre-meeting workflow. I’d build an account snapshot ahead of time as that rep, keyed by their permission signature, but recheck current territory and field access before serving it. A router chooses the snapshot, reviewed CRM operations, or hybrid search. Every fact and opportunity risk comes from fetched, authorised evidence. External drafts pass a blocking approved-claims check; CRM changes are previewed and approved before an idempotent tool call. I’d start read-only, test cross-territory access and claim-level failures, then expand only when critical slices, adoption, latency, and cost hold.”
| Follow-up | Short answer |
|---|---|
| Fabricated customer fact? | Claim-level citations to fetched records; abstain on missing data; block external claims. |
| Rep changed territory? | Invalidate snapshot, recheck fresh policy at serve time. |
| Why not a model-generated CRM query? | Fixed reviewed operations bound fields, rows, and permission scope. |
| Why not direct write? | Exact-field preview, approval, idempotency, audit. |
| Slow account prep? | Calendar precompute and bounded deterministic ask path. |
Final mental model: Authorised sources → precompute as rep → reauthorise at ask → route evidence → cite and verify claims → preview and approve any write.
Technical Deep Dive · 8 min — Read after the Interview Guide. The detail behind each component, for follow-up questions.
Use the Main guide for the spoken answer. This is the technical backup; the unchanged source case keeps the full synthesis, interview script, and references.
Model and agent roles: Deterministic routes handle common snapshots, CRM (customer relationship management) counts, and exact lookups; a bounded agent path handles ambiguous multi-step asks. The LLM (large language model) copilot summarises and drafts from authorised evidence, while the claim verifier and approval gateway control external claims and CRM writes.
1. Source and permission map
| Source | Authority and freshness | Permission detail and failure |
|---|---|---|
| Salesforce/HubSpot CRM | Accounts, opportunities, contacts, activities; minutes via change events and reconciliation | Org-wide defaults, owner, role hierarchy, territory, sharing rules for records; field-level security for fields. Wrong scope leaks peer pipeline or stale stage. |
| Gong/Zoom calls | Participant statements; hours after a call | Participant/manager access and regional recording consent; PII and injection in transcripts. |
| Email/calendar | Threads, invites; near real time | Mailbox owner or explicit delegation; never read another rep’s mailbox. |
| Product docs | Approved feature descriptions; updated by product marketing | Some partner-only; superseded features and roadmap claims are dangerous. |
| Pricing/discount policy | Deal-desk rules, versioned | Regional variants and thresholds; no out-of-policy promise. |
| Support history | Account tickets/escalations | Account/tenant scope; severity can be mis-summarised. |
| Warehouse | Usage, ROI pilots, renewals; often daily | Row-level account/role scope; internal ROI is not an approved external claim. |
Each record needs stable ID, owner, updated time, and ACL (access control list) metadata; exclude unmapped sources. User feedback is not ground truth until SME (subject-matter expert) approval. The source notes that its detailed CRM permission model and structured router are additions to the pack based on cross-cutting references, not claims made by the practice worksheet alone.
2. Identity and CRM sharing mirror
Validate the customer IdP token’s signature, issuer, audience, and expiry, then map customer groups into local roles. Alert on group-mapping drift; provision a new user only to their own tenant with minimal rights. The CRM mirror carries owner_id, territory_ids, role visibility, sharing rules, and field masks for sensitive fields such as amount. Compile tenant, territory, and role into the retrieval pre-filter. Recheck live attributes and field masks after retrieval and before generation or serving a snapshot. A count or aggregate containing forbidden rows violates the same zero-leak gate as a document excerpt.
Connector credentials are vault references, resolved at use time, never written into model prompts or traces. Scope each connection to one customer and use per-tenant encryption boundaries where required. Embeddings and snapshots are derived state, not authorisation authority.
3. Snapshot as a materialized view
Calendar trigger or on-demand job builds summary, open opportunities/stage/next step, recent calls and emails, support escalations, segment objections, and approved claims. Run the job as the rep, key cache on account plus permission signature, and stamp source/index/policy versions. A manager and rep on the same account may get different snapshots. On role or territory change, invalidate affected snapshots. At serve time, reauthorise with current attributes; if the CRM is down, show a permitted last snapshot with staleness labelling or refuse. Precompute improves p95 but cannot preserve access after revocation by itself.
At 10× accounts, shard jobs by territory and make connector schedules independent so one rate-limited source does not block others. Interactive load should scale with snapshot hit rate rather than live CRM fan-out.
4. Structured versus semantic routing
| Question | Route |
|---|---|
| “Summarise the last three calls” | Semantic/hybrid retrieval on authorised transcripts. |
| “How many open opportunities missed close date?” | Fixed structured CRM query over authorised rows. |
| “Status of opportunity ID 0065g00000?” | Direct exact-ID lookup. |
| “Objections across late-stage deals this quarter?” | Structured filter first, then summarise matching prose. |
Use reviewed operations such as get account by ID, opportunities by stage, interactions since a date. Free-form natural-language query generation can invent fields or scan too broadly. Opportunity risk logic uses fetched stage age, moved close date, competitor mention, unanswered emails, open escalations, and playbook objections; each risk carries a source. Missing fields or stale transcripts become explicit gaps.
5. Claim and write boundaries
Playbook.approved_claims is the source for outbound claims. Pricing uses the current deal-desk policy. The claim verifier blocks an external draft if a claim has no approved entry or correct citation; “warn” is insufficient for pending certifications, internal ROI, or unapproved customer references. Discovery questions and personalization may use the rep’s account interactions and approved playbook, never model stereotypes.
Draft.approval_status controls write-back. A CRM update proposal lists exact field changes, receives a policy check and preview, then a human approves an idempotent tool-gateway call. Audit the approval and receipt. Mail sending, closing an opportunity, and changing amount/stage are above the day-one threshold. A later clean pilot may justify auto-approval for a low-risk field such as last_contacted; the first release does not assume that permission.
6. Failure decisions
| Failure | Decision |
|---|---|
| CRM unavailable | Labelled authorised snapshot if within allowed staleness; no writes. |
| Policy engine, ACL mapping, or approval down | Fail closed. |
| Missing evidence or stale source | List what was not checked; abstain or escalate. |
| Unapproved claim or price | Block external draft, not merely warn. |
| Transcript/email injection | Content is untrusted evidence; it may still sway the model, so tools and policy stay gated outside it. |
| Vector path unavailable | Use authorised keyword/structured path where supported and label limitation. |
| Model route down | Queue draft/long work with progress, or use approved fallback. |
Trace source IDs, retrieval/policy versions, field masks, citations, model/prompt versions, claim verdict, approval, and write receipt. Control-plane settings include connector registry, ACL mirror, approved claims, pricing policy, tool allowlist, evaluation suites, and budgets.
7. Evaluation and release
Use SME-approved historical account briefs and sparse-record cases, permission red-team questions from reps/managers across territories, exact citation audits, claim-level labels, and workflow replay. Example source thresholds: groundedness ≥90%, citations ≥95%, target task completion ≥80%, high-risk escalation ≥95%, zero permission violations, and zero critical failures on regulated-claim slices. Agree thresholds before release; treat the critical slices as separate gates.
Measure prep-time reduction, seller adoption, brief accuracy, citation coverage, meeting quality, conversion where attributable, p95, and cost/workflow. Online monitor unsupported-claim rate by model route, source, and claim category. User corrections enter evaluation after review; they are not direct training data.
Rollout: one CRM connector and territory matrix; historical golden set; offline no-write prototype; shadow mode; read-only pilot; draft-only workflow with approved write-back; expansion after safety and value hold. Keep model version pinning, canary, rollback, and source-owner sign-off.
8. Latency pivot
The source drill starts with 30–45 s account prep. The likely driver is serial tool calls and agent steps, not necessarily model inference. Trace the graph, then precompute the account snapshot, route common questions deterministically, parallelise independent read-only calls, cache permission-scoped state, cap steps/top-k/timeouts, and use the agent only for ambiguous next steps. Track agent step count, tool latency, snapshot hit rate, timeout rate, p95, and cost/workflow. A real-time in-call assistant is a distinct G16 problem with stronger precompute/stream/async split.
9. Model regression incident
On the source’s 2026-07-08 scenario, llm_standard_v2 changed to llm_premium_v3. Persuasive drafts began claiming a pending SOC 2 renewal and a 34% support-cost reduction from an internal pilot. Online unsupported-claim rate reached 8.7% versus 1.2% baseline (sample 430, 37 external-policy failures). The offline suite passed 96.7% of 120, but its six regulated-claim cases passed only 83.3% and omitted pending security, internal ROI, and customer-logo permission cases. The verifier had been weakened to warn-only.
Detect: compare online failures with offline slices and policy action. Contain: roll back model route, restore block mode, flag experiment drafts for review. Root cause: stronger extrapolation, weak critical-slice coverage, weakened policy gate. Prevent: claim-level labels, independent critical-slice release gates, negative examples that must refuse, online unsupported-claim monitoring, and no warn-only external-claim route. The failure is in evaluation and release control, not just prose style.
10. Interview trade-offs
| Choice | Reason | Revisit if | |---|---| | Precompute snapshot, reauthorise at serve | Removes source fan-out from hot path without freezing permissions. | Most meetings unscheduled; build a fast partial snapshot on open. | | Fixed CRM operations | Bounds fields, rows, and authorisation. | Validated open-ended query layer is genuinely needed. | | Block unapproved external claims | Legal/commercial risk exceeds draft convenience. | Internal-only notes may use warnings; external drafts still block. | | Preview and approve writes | Changes are consequential and auditable. | Proven low-risk field update earns a narrower automated route. |
The source retains the original sixty-minute script, detailed source attribution, and trace excerpt.
Quick Review · 3 min — The whole case on one page, for recall before an interview. Assumes the guide.
Use the Main guide to practice speaking and the Deep Dive for mechanisms. The source is the full reference.
One sentence
Build the brief before the meeting as the rep, recheck access when serving it, cite every fact, block unapproved external claims, and preview every CRM (customer relationship management) write.
Five outputs by risk
Account summary + opportunity risks: read-only. Discovery questions + email drafts: draft-only. CRM update suggestion: preview and approval before write-back.
Ask first
Workflow and decision? Who uses/reviews? Which tasks read/draft/write? Which sources and permissions? Approved claims and prices? Refusal cases? 30-day pilot metric? Audit proof?
Three lanes
Precompute: sources → ACL/territory mirror → structured store + hybrid index → snapshot as rep → permission-keyed cache.
Ask: SSO/role/territory → route → authorised evidence → fresh post-check → cited answer/draft → claim verifier.
Write: proposed exact fields → preview → human approval → allowlisted idempotent gateway → CRM receipt.
LLM/agent role: The copilot LLM (large language model) summarises and drafts; a bounded agent handles ambiguous steps. Common CRM lookups are deterministic, and the model cannot approve claims or writes.
Rules
- Snapshot is a materialized view, not an authorisation decision; recheck after territory change.
- CRM org-wide defaults, owner, role hierarchy, territory, sharing rules, and field masks all matter.
- Structured counts and ID lookups use reviewed CRM operations, not vector similarity.
- Opportunity risk comes from fetched fields and interactions, not model memory.
- External claims require approved playbook/policy evidence; verifier blocks.
- Permission uncertainty and approval failures close the path.
Source targets
Interactive 3–8 s. Example gates: ≥90% grounded claims, ≥95% citations, ≥80% task completion, ≥95% high-risk escalation, zero permission violations and zero critical unsupported external claims.
Failure card
CRM down → authorised stale snapshot labelled, no writes. Territory changed → invalidate and reauthorise. Missing fact → say so. Price/certification unapproved → block draft. Injected email/transcript → untrusted data; write tools stay gated outside the model.
Rollout
One connector + territory matrix → offline golden set → shadow → read-only pilot → approved drafts/writes. Gate critical claim slices independently; measure rep adoption and prep-time reduction too.
Latency answer
30–45 s prep likely comes from agent steps and serial tools (confirm in traces). Precompute, deterministic route, permission-scoped cache, parallel safe reads, bounded graph. Measure step count, tool time, cache hit, p95, cost/workflow.
Regression card
Aggregate 96.7%/120 concealed regulated claims 83.3%/6. Online unsupported claims 8.7% vs 1.2% after model upgrade and warn-only verifier. Roll back route, restore block, add claim-level critical gates.
Interview close
“The system is useful only when the rep trusts both the account facts and the boundary around them: authorised evidence, approved claims, and approved writes.”
Full Design 1 · 9 min — The complete, referenced write-up behind the other tabs. The sources for every tab live here.
An assistant that knows the account better than the rep, without ever seeing more of the CRM (customer relationship management) than the rep may.
The hard part of a sales copilot is not summarising an account. It is that every useful answer touches CRM records, call transcripts and pricing policy permissioned by territory, role and deal stage. One invented customer fact or unapproved claim can reach a customer's inbox. This page consolidates the group's prompts into one read for the day before. The group has no bespoke worked design, only a templated practice worksheet, so the CRM-permission and account-data detail here is added for this pack and marked where it appears.
| Case in the group | What it contributes here |
|---|---|
| #28 Sales Copilot for Account Executives (anchor) | Sections 1 to 12: the worksheet, answer key, requirements, evaluation, rollout and spoken answer |
| #48 OpenAI Q4 AI-Powered Sales or Account-Research Assistant | The explore list and success metrics in sections 1 and 10, the fabricated-fact follow-up in section 12 |
| #40 Reduce latency for an agentic CRM assistant | Section 13 |
| Incident 7, model regression missed by a weak eval suite (mapped to G13 in the sheet, walked here because it is a sales copilot) | Sections 10 and 14 |
| Handbook Module 06 docs 1 and 5 (identity, connectors, structured-data router) | The permission and CRM-connector detail in sections 3, 6 and 7 |
1. Name the Workflow and the Risk Boundary Before Drawing Anything
Do not start with the model. Start with the workflow. Which B2B (business-to-business) sales workflow is slow, risky or inconsistent today? Who decides at the end of it? Which risk cannot be automated? A copilot that saves ten minutes and sends one unapproved claim has lost more than it saved. So the risk boundary is named before the first box.
The workflow is the pre-meeting hour. An account executive prepares for a meeting. They ask for an account summary, the opportunity risks, suggested discovery questions, email drafts and CRM update suggestions. Each of those five outputs sits on a different side of the risk boundary. The summary and risks are read-only assistance. The questions and drafts are draft-only. The CRM update is an action, and it needs explicit approval before write-back.
The three answer tiers show what the framing buys. The weak answer connects the documents to a vector database, uses an LLM (large language model) to answer questions and adds a chatbot UI. It ignores the workflow, the permission boundaries, source freshness, evaluation, human approval and monitoring. The average answer builds RAG (retrieval-augmented generation) over the company data, adds citations and tests with sample questions. It never separates low-risk assistance from high-risk actions, never defines the data model or permission checks, and never explains rollout gates. The strong answer maps the workflow and the risk boundary first, then designs a permission-aware system. It ingests approved sources with metadata, freshness and ACLs (access control lists). It uses hybrid retrieval with pre-generation permission filtering, generates cited answers, exposes uncertainty and missing evidence, and routes risky actions to human approval. It proves the system with golden cases, permission red-team tests, groundedness and citation metrics, latency and cost budgets, and a staged rollout from offline prototype to approved write-back.
Ask the questions that decide the design and write the answers where they stay visible.
| Question to ask | What the answer decides |
|---|---|
| What exact sales workflow is slow, risky or inconsistent today, and what decision does the user make at the end of it? | The five outputs and which side of the risk boundary each sits on |
| Who is the primary user, who reviews the output, and who owns the operational risk if the assistant is wrong? | The approver for drafts and CRM writes; the trace store's audience |
| Which tasks are read-only, which are draft-only, and which need explicit approval before write-back? | The tool allowlist and the approval gate |
| Which systems hold the trusted source of truth, and how do their permissions, freshness and ownership differ? | The connector map and the permission model per source |
| What are the top five recurring cases by volume and the top five highest-risk cases by impact? | Which requests get a deterministic route and which need the agent |
| What does a successful 30-day pilot prove: less handling time, higher accuracy, better compliance, fewer escalations, or satisfaction? | The success metrics agreed at intake |
| What must the assistant refuse or escalate instead of generating? | Pricing promises, unapproved claims, competitor facts without a source |
| What audit evidence must exist so security, legal or management can reconstruct why the system answered as it did? | The audit log schema |
Map the people, because each notices a different failure first.
| User | Workflow | Failure they notice first | What the copilot gives them | Approval needed |
|---|---|---|---|---|
| Account executive | Prepares for the meeting, asks for summary, risks, questions, drafts, CRM updates | A wrong or invented account fact | A cited account brief, risk list grounded in CRM fields, drafts from approved messaging | None for read-only; every draft is theirs to send; every CRM write is previewed |
| Sales manager / reviewer | Reviews pipeline hygiene and outbound claims | A polished draft with an unsupported claim | Claim-level flags, escalation reasons, pipeline updates as proposals | Approves high-risk drafts and writes above the threshold |
| Admin / security | Owns CRM permissions, connector credentials, audit export | A rep seeing an account outside their territory | Permission-aware retrieval, connector registry, immutable audit | Signs off each source and each write tool |
| Executive sponsor | Tracks adoption and time saved | A tool nobody opens before meetings | Preparation-time reduction, adoption, conversion and meeting-quality metrics | Approves rollout stages |
The practice-set version of this prompt (a likely OpenAI-style case, not an official question) asks for account briefs. It lists what to explore:
- CRM, email, product-usage, support and public-data integrations
- entity resolution
- freshness and source prioritisation
- permission boundaries
- citation and provenance
- personalisation
- human review
- measuring seller adoption and time saved
Every item lands in a section below.
2. State Requirements as Testable Constraints
A requirement the customer cannot test is a preference. "Make the brief accurate" is a preference; "90 percent of claims supported by cited evidence, zero permission violations" is a constraint, and only the second changes the architecture. Split the functional list with MoSCoW so the launch gate is the smallest set that keeps the promise.
The must-haves are four. Support the core workflow: account summary, opportunity risks, discovery questions, email drafts and CRM update suggestions, in that order of risk. Return grounded answers with citations to approved source systems, and never answer an unsupported claim confidently. Apply user, role, tenant, region and sensitivity permissions before retrieval and again before final generation. Keep every write tool behind a preview and a human approval.
The should-haves belong in the first usable version. Show confidence, missing evidence and the escalation reason when the system is uncertain or the policy risk is high. Collect user feedback and reviewer corrections for evaluation, never for training without governance. Provide admin controls for source inclusion, document freshness, policy rules, blocked actions and audit export. Precompute the account snapshot before the meeting so the interactive path stays fast. Personalisation by segment and playbook, public-data enrichment, and conversion attribution can wait.
Declare the non-goals, because a sales copilot sprawls into a CRM replacement if nobody stops it:
- sending email on the rep's behalf
- writing to the CRM without a previewed, approved draft
- quoting prices or discounts outside the approved policy
- scoring or ranking leads (biased lead scoring is a named red-team risk)
- reading accounts outside the rep's territory or role
- long-term memory of a customer beyond the CRM record
The non-functional requirements are the operating constraints, stated so a test can fail them.
| Constraint | Stated so it can be tested |
|---|---|
| Latency | In this design, interactive answers in 3 to 8 seconds for normal questions. Longer workflows go asynchronous with progress state. The pre-meeting brief is precomputed, so the interactive ask reads a snapshot rather than fanning out to the CRM |
| Availability | Business-critical selling hours. Graceful degradation if the LLM, the vector store or the CRM is down: serve the last snapshot with a staleness label, or refuse |
| Cost | Token budgets, caching of stable documents, retrieval pruning, small models for classification, expensive reasoning only where the risk justifies it. Reported as cost per workflow |
| Security and privacy | SSO, RBAC and ABAC, source-level ACLs, encryption in transit and at rest, secrets management, no training on customer data unless the contract allows it |
| Audit and compliance | Immutable logs of queries, retrieved evidence, model version, policy decisions, approvals and final output |
| Reliability | Fail closed on permission uncertainty, stale data, missing citations and high-risk write actions |
Every must-have needs an owner in the architecture.
| Requirement | Primary component(s) |
|---|---|
| Five outputs by risk order | Intent router, snapshot service, draft generator, CRM write proposer |
| Grounded answers with citations | Approved-claims retriever, evidence selector, citation builder, claim verifier |
| Permissions before retrieval and before generation | Identity gateway, CRM permission mirror, ABAC pre-filter, policy post-check |
| Write tools behind preview and approval | Tool gateway, allowlist, draft store with approval status, idempotency keys |
| Confidence and escalation shown | Grader, output policy engine |
| Feedback for evaluation only | Feedback store separated from ground truth, SME approval step |
| Admin controls and audit export | Control plane, audit log |
| Precomputed snapshot | Scheduled snapshot job, snapshot cache keyed on account and rep permission signature |
Full Design 2 · 11 min — The complete, referenced write-up behind the other tabs. The sources for every tab live here.
3. Map Every Source With Its Permission Model
The answer key names the sources: Salesforce or HubSpot, Gong or Zoom transcripts, email and calendar, product docs, pricing and discount policy, customer support history, and the data warehouse. What it does not say is how each one is permissioned, and that is the part the interviewer probes. The permission model per source below is added for this pack. The freshness column is my working assumption for a typical setup, not a vendor figure.
| Data source | Format | Owner | Freshness | Permission model (added) | Risk |
|---|---|---|---|---|---|
| CRM (Salesforce / HubSpot) | Accounts, opportunities, contacts, activities, notes | Sales operations | Minutes; change events plus nightly reconciliation | Record access: org-wide defaults, owner, role hierarchy, territory, sharing rules; field-level security on amount and other restricted fields | A rep seeing a peer's territory; forecast fields leaking; stale stage after a close |
| Call transcripts (Gong / Zoom) | Transcript text, participants, timestamps | Sales enablement | Hours after the call | Participant and manager access; recording consent by region | PII and customer confidences; prompt injection in what a customer said |
| Email and calendar | Threads, invites, attendees | Individual mailbox owner | Real time | Mailbox owner only, delegated access explicit | Reading another rep's mailbox; injection in inbound mail |
| Product docs | Pages, PDFs | Product marketing | Days | Internal, some partner-tier | Superseded features; internal roadmap leaking into customer drafts |
| Pricing and discount policy | Policy docs, approval matrices | Deal desk | Weeks; versioned | Internal; regional variants | Disallowed pricing promises; stale discount thresholds |
| Support history | Tickets, escalations | Support | Minutes | Account-scoped; tenant-scoped in multi-tenant support | Cross-account leakage; severity fields mis-summarised |
| Data warehouse | Usage metrics, ROI pilots, renewals | Analytics | Daily | Row-level by account and role; internal-only pilot results | Internal-only ROI numbers used as external claims (the incident) |
State the integration assumptions aloud. Every source record has a stable ID, owner metadata, a last-updated timestamp and access-control metadata. A source that lacks ACL (access control list) metadata is excluded from production retrieval until it is mapped. Embeddings are not the authority for permissions; permissions are checked through metadata filters and, for sensitive records, through source-system authorisation checks. Source freshness varies by system, so the answer shows a stale-source warning when a record is older than the approved threshold. User feedback is stored separately from ground truth, and SME-reviewed corrections become evaluation data only after approval.
The core records follow. Account(id, segment, industry, region, owner, entitlements). Opportunity(id, stage, amount, close_date, competitors, next_step). Interaction(id, account_id, type, transcript, participants, timestamp). Playbook(id, segment, approved_claims, objections). Draft(id, account_id, user_id, content, approval_status). AuditLog(user_id, account_id, source_ids, output_type). Two of these carry the safety story: Playbook.approved_claims is the only place an outbound claim may come from, and Draft.approval_status is the gate every write passes through.
4. Draw the Architecture End to End
One diagram carries the whole design. The organising split is control plane against data plane. Inside the data plane, two lanes must never share a hot path. The pre-meeting precompute lane is slow and scheduled. The interactive ask lane reads what precompute produced. Write-back is a third, gated lane.
 ╔══════════════════════════════ CONTROL PLANE (changes are releases) ══════════════════════════════╗
 ║  ABAC policy + CRM sharing-rule mirror · connector registry + schedules · credentials (vault refs) ║
 ║  approved-claims playbooks · pricing policy versions · prompt / model / route versions              ║
 ║  tool allowlist + approval thresholds · eval suites incl. claim-level slices · budgets              ║
 ╚═══════════════════════════════════════╤═══════════════════════════════════════════════════════════╝
                                         │ configures every box below
 ╔══════════════════════════════ DATA PLANE (calls are requests) ═══════════════════════════════════╗
 ║                                                                                                   ║
 ║  PRECOMPUTE — scheduled, before the meeting                                                       ║
 ║   CRM · transcripts · email/calendar · docs · pricing · support · warehouse                        ║
 ║        │ change events + nightly reconciliation (connector registry, one schedule per source)     ║
 ║        v                                                                                          ║
 ║   connectors ─> normalise ─> ACL + territory mirror ─> chunk / embed ─┬─> keyword + vector index   ║
 ║                                     │ refuse: no usable ACL           └─> structured store (CRM)   ║
 ║   calendar trigger ─> SNAPSHOT JOB: summary · open risks · last interactions · approved claims     ║
 ║                       (built as the rep, permission-checked, cached on account + rep signature)    ║
 ║                                                                                                   ║
 ║  ASK — synchronous, ordered by risk                                                               ║
 ║   rep ─> gateway ─> AUTHORIZE ─> ROUTE ─> FETCH ─> ENFORCE ─> REASON ─> GENERATE ─> VERIFY ─> answer
 ║           SSO      resolve      intent:   snapshot   ABAC     risks from  cited      claim +      ║
 ║           via      role,        summary   cache;     post-    CRM fields; brief,     citation     ║
 ║           IdP      territory,   risk      structured check,   playbook    questions, check,       ║
 ║                    deal stage   draft     query or   redact   objections  draft      output       ║
 ║                                 update    hybrid                                     policy       ║
 ║                                           search                                         │        ║
 ║                                                                     insufficient / unapproved     ║
 ║                                                                     claim ─> REFUSE + escalate    ║
 ║                                                                                                   ║
 ║  WRITE-BACK — gated                                                                               ║
 ║   proposed CRM update or email draft ─> policy check ─> PREVIEW to rep ─> APPROVE ─> tool gateway ║
 ║   (allowlist, idempotency key) ─> CRM / mail ─> audit                                              ║
 ║                                                                                                   ║
 ║  OBSERVABILITY — every stage writes                                                               ║
 ║   trace store ─> eval service (golden set · claim-level slices · permission red team · shadow)     ║
 ║               ─> dashboards (unsupported-claim rate · permission violations · step count ·         ║
 ║                  snapshot hit rate · cost per workflow · adoption)                                 ║
 ╚═══════════════════════════════════════════════════════════════════════════════════════════════════╝
The same flow as a rendered diagram:
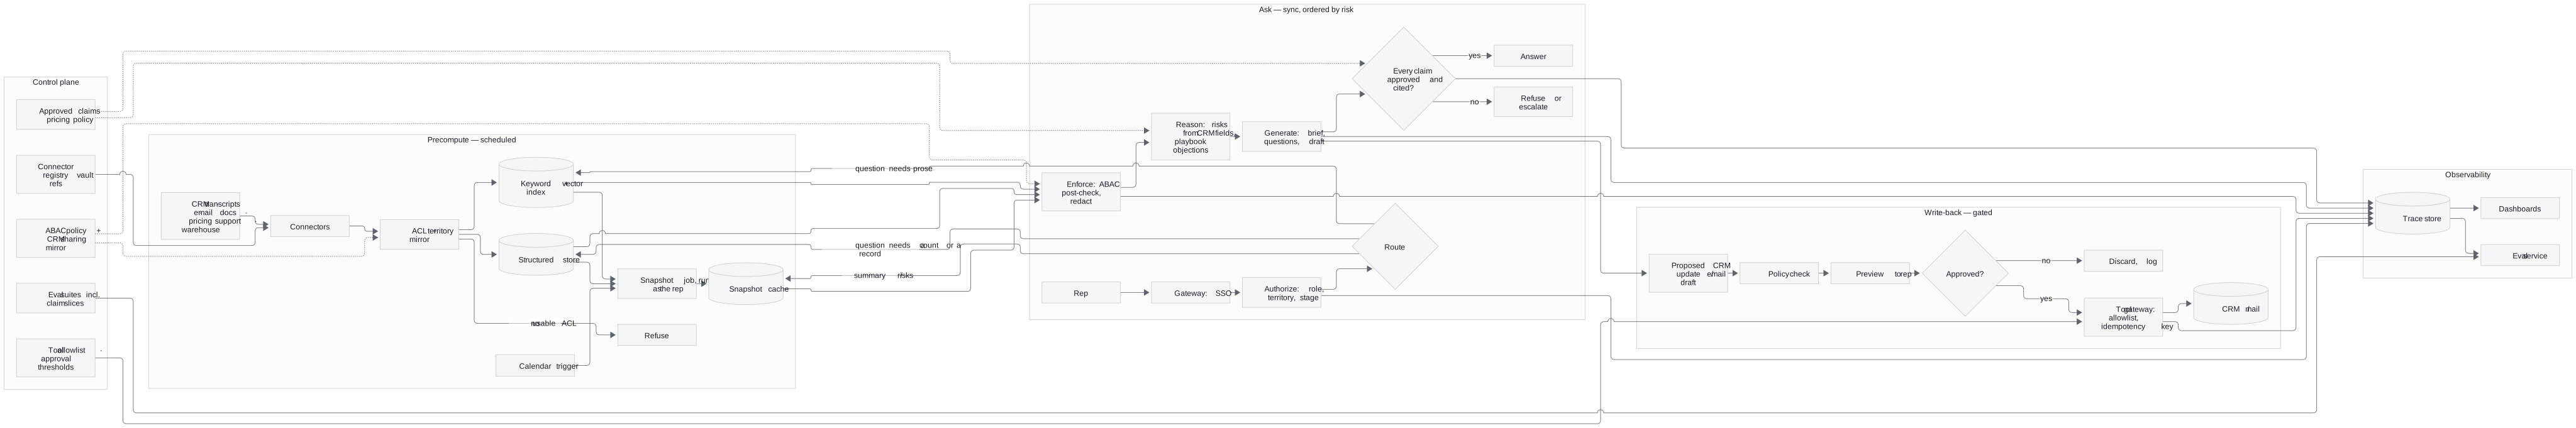
Read the components in dependency order, because that is the order they exist and the order they fail.
| Component | Responsibility | Fails how |
|---|---|---|
| Identity gateway | Validate the SSO token, load role, territory, tenant and deal-stage context, classify the request as read-only, draft-only or action-taking | Closed: no identity, no answer |
| Connector registry | One schedule and one credential reference per source; change tokens where the source API supports them; health as its own signal | Degrades: one source's outage is quarantined to that source |
| ACL and territory mirror | Translate CRM sharing rules, field-level security and transcript participant access into one attribute model | Closed: no usable ACL, not indexed |
| Snapshot job and cache | Build the brief before the meeting as the rep, cache it keyed on account plus the rep's permission signature | Degrades: serve the last snapshot with a staleness label |
| Intent router | Decide summary, risk, draft or update; decide structured query versus semantic search versus both | Degrades: fall through to the agent path |
| Structured store and indexes | CRM fields for counts, lookups and stage; documents and transcripts for prose | Degrades: keyword when vector is down, labelled |
| Policy post-check | Re-run ABAC on fresh attributes; redact PII from transcripts as an obligation | Closed: policy engine down, refuse |
| Reasoning layer | Risks from CRM fields and playbook objections; never from model memory | Refuses when evidence is missing |
| Claim verifier and output policy | Every outbound claim traced to an approved-claims entry; block, never warn, on external claims | Closed on an unapproved claim |
| Tool gateway | Allowlist, idempotency keys, preview, approval, audit | Closed: no approval, no write |
| Trace store, eval, dashboards | Replayable runs, claim-level slices, permission red team, online unsupported-claim monitor | Degrades: answer served, gap logged |
Three boundaries are worth pointing at while the diagram is up. The precompute-versus-ask boundary keeps CRM fan-out off the interactive path. The trust boundary sits at ENFORCE: everything to its left may hold records the rep cannot see, nothing to its right may. The write boundary sits at APPROVE: nothing reaches the CRM or a mailbox without a previewed, approved draft carrying an idempotency key.
5. Precompute the Account Snapshot Before the Meeting
The interactive path cannot fan out to the CRM, the transcript store and the warehouse on every question. A meeting is on the calendar hours in advance. So the brief is built then, not when the rep opens the panel. That single decision is what makes the 3-to-8-second target and the latency drill in section 13 achievable.
The snapshot job runs on a calendar trigger, or on demand with a visible progress state. It builds the account summary, the open opportunities with stage and next step, the last interactions across calls and email, the open support escalations, and the approved claims and objections for the account's segment. It runs as the rep, so the permission check happens at build time. It is cached keyed on the account and the rep's permission signature. A manager and a rep on the same account get different snapshots. They may see different fields.
Precomputation is an optimisation, never a permission model. A snapshot is a materialised view, and a materialised view can outlive a permission change: a rep moved off a territory at noon must not read the 9 a.m. snapshot at 2 p.m. So the ask lane re-checks the policy on fresh attributes before serving it, and a territory or role change invalidates every snapshot keyed on that rep. Say that sentence in the room; it is the same two-layer rule as permission-aware RAG (retrieval-augmented generation).
6. Propagate CRM Permissions and Territory Rules Into Retrieval
This section is added for this pack. The answer key says "apply user, role, tenant, region and sensitivity permissions before retrieval" and stops there. The material below draws on Handbook Module 06 docs 1 and 5.
Identity is established before any permission logic runs. Authenticate through the customer's own identity provider, validate the token's signature, issuer, expiry and audience, and map the customer's own groups into the platform's role vocabulary rather than inventing roles locally. Group mapping is configuration that can drift, so a renamed group on the customer's side must surface as an alert, not silently orphan a rep. A user from a newly connected customer is provisioned just in time from the token's claims, scoped to their company, never with more access than intended by default.
CRM permissions are richer than document ACLs, and the mirror has to carry all of them. Salesforce decides record visibility by org-wide defaults, owner, role hierarchy, sharing rules, teams and territories, and field-level security decides which fields show. The mirror translates each into an attribute on the record: owner_id, territory_ids, role_visible_from, and a field mask that hides forecast amount, or any other FLS-restricted field, from roles that cannot see them. The pre-filter compiled into retrieval carries tenant, territory and role; the post-check re-verifies the field mask and any sharing rule that changed since the index was written. A structured leak is still a leak: a count of open opportunities that includes a peer's territory is as serious as a forbidden document, and it is held to the same zero-violation gate.
Credentials for the CRM, the call recorder and the mailbox are references to a vault, never values. They are resolved at the moment of use, never logged, never written into a trace, and scoped per connection rather than per connector type, so one customer's Salesforce credential can never reach another customer's Salesforce. Per-tenant encryption keys mean one leaked key exposes one tenant, not all of them, and a tenant's data can be crypto-shredded by destroying its key.
The interview lens, in one line:
"Authorisation logic assumes identity is already established. In front of it I validate the customer's own token and map their groups. Underneath it, credentials come from a vault by reference and never appear in a trace."
7. Ground Opportunity Risks in CRM Fields, Not Model Memory
"What are the risks on this opportunity?" is a structured question wearing a conversational coat. Embed it and search a document index, and the answer is the most similar-sounding notes. It is not the stage that has not moved in 40 days, the competitor named in the last call, or the close date that slipped twice. Semantic search answers "which things are like this", never "how many", "which is most recent" or "did this field change". A router in front of retrieval decides which kind of question this is.
| Question shape | Right tool | Why plain search fails |
|---|---|---|
| "Summarise the last three calls with this account" | Semantic search over transcripts | — |
| "How many open opportunities does this account have past their close date?" | A structured query on CRM fields | Search returns similar records, not a count |
| "What is the status of opportunity 0065g00000?" | Direct lookup by ID | An ID is not ordinary text |
| "Which objections came up across all late-stage deals this quarter?" | Both: filter first, then summarise the filtered transcripts | A filter cannot summarise prose; search cannot scope to "this quarter's late-stage deals" |
Prefer a fixed set of reviewed operations on the CRM over generating queries from natural language: get opportunities by stage, get account by ID, get interactions since a date. A model that generates a query can invent fields or touch every row, and "the copilot queried the whole pipeline" is a real incident. The fixed operations are the tool registry pointed at a record system, and they are the same allowlist the tool gateway enforces.
Opportunity risks are then reasoned from evidence the system fetched: stage age, slipped close dates, competitor mentions in transcripts, unanswered emails, open escalations, and the playbook's known objections for the segment. Each risk carries its citation. When the fields are missing or the transcripts are stale, the copilot says so and lists what it could not check, rather than filling the gap from what a typical deal looks like.
Full Design 3 · 11 min — The complete, referenced write-up behind the other tabs. The sources for every tab live here.
8. Draft From Approved Claims and Preview Every Write
An email draft is the copilot's most visible output. It is also the most dangerous one, because it leaves the building. The rule is that every outbound claim traces to an entry in the approved-claims playbook, and the claim verifier blocks rather than warns on anything it cannot trace. Pricing and discount language comes only from the versioned policy, and the copilot refuses to quote outside it.
Personalisation is drawn from the account's own record and interactions: the rep's last thread, the customer's stated priorities from the transcript, the open escalation. It is never drawn from the model's sense of what a company like this probably cares about. Discovery questions follow the same rule, generated from the playbook's objection list and the gaps in the CRM (customer relationship management) record.
CRM update suggestions are proposals, not writes. The copilot proposes a stage change, a next step or a note. The rep sees a preview of the exact fields that would change. Approval routes the write through the tool gateway with an idempotency key, so a retried approval cannot write twice. Read tools run automatically. Write tools require a policy check, an idempotency key, preview mode and human approval for anything above the risk threshold. Sending mail, closing an opportunity, changing an amount and emailing externally sit above the threshold on day one.
10. Gate the Release on Claims, Not Fluency
An eval suite that measures grammar, tone and general groundedness will pass a model that writes beautifully and invents a security certification. The scenario incident in section 14 is exactly that: a 96.7 percent pass rate on 120 cases hid an 83.3 percent pass rate on the six regulated-claim cases that mattered. The gate therefore has slices, and the critical slices pass independently or the release does not ship.
| Metric | Good threshold | Bad threshold | Test dataset | Owner |
|---|---|---|---|---|
| Answer groundedness | ≥ 90% supported claims | < 80% | Golden Q&A plus SME review | FDE / SME |
| Permission violations | 0 | > 0 | Red-team set: same question from users with different roles, territories, tenants | Security |
| Citation accuracy | ≥ 95% correct citations | < 85% | Source-span audit of sampled drafts | SME |
| Task completion | ≥ 80% of target workflows completed with less manual effort | < 65% | Workflow replay tests | Product |
| Escalation quality | ≥ 95% correct escalation on high-risk cases | Missed high-risk case | Risk-labelled scenarios | Product / support |
| Unsupported-claim rate (added, from the incident) | Zero critical failures on regulated-claim slices; online rate at baseline | Any pending-approval or internal-only claim in an external draft | Claim-level suite: security certifications, ROI numbers, customer references, with negative examples the model must refuse | Legal / enablement |
| Latency and cost | p95 within target; cost per workflow below budget | Breach at peak | Load test plus production telemetry | Platform |
The OpenAI-style practice version adds the business metrics that prove adoption: preparation-time reduction, brief accuracy, citation coverage, sales-representative adoption, conversion improvement and meeting-quality improvement. Report them beside the safety metrics, because a copilot that is safe and unused has also failed.
Red-team the boundary directly:
- invented customer facts and disallowed pricing promises
- confidential account leakage across territories and tenants
- biased lead scoring, which is why scoring is a non-goal
- indirect prompt injection hidden in transcripts, email threads, tickets or uploaded files
- data exfiltration: summarise every account in the region, expose hidden metadata, reveal the tool schema
- unsafe automation: close, approve, refund, email externally, change priority without approval
- staleness and conflict: an old discount policy contradicting the current one, where the system must surface the conflict and prefer the approved current source
11. Roll Out From Read-Only to Approved Write-Back
Week one is not the whole diagram. It is one CRM connector, the territory mirror provably right for three reps in three territories, a golden set built from historical account briefs with the enablement team, and the permission red team standing.
| Week | Gate |
|---|---|
| 0-1 | Define the workflow, the risk boundary, success metrics, source owners, approval rules and non-goals |
| 1-2 | Ingest a limited approved corpus; offline prototype with no write-back and no external communication |
| 2-3 | Golden dataset from historical cases and SME-approved answers; red-team and permission tests; claim-level slices |
| 3-4 | Shadow mode against historical and live cases; compare with the rep's own briefs without showing output |
| 5 | Read-only pilot with citations, confidence, feedback capture and an escalation path |
| 6-8 | Draft-only workflow actions behind human approval; every high-risk action stays gated |
| After | Expand sources and users only while eval metrics, incident rate, latency and cost hold; keep the rollback plan |
Close on the trade-offs and what would change them.
| Decision | Chose | Would revisit if |
|---|---|---|
| Precomputed snapshot over live fan-out | Precompute on the calendar trigger, re-check permissions at serve time | Meetings were mostly unscheduled, then a fast partial snapshot on open |
| Fixed CRM operations over NL-to-query | Fixed, reviewed operations through the tool gateway | The question set were genuinely open-ended and a validated query layer existed |
| Block over warn on unapproved claims | Block | Never for external drafts; warn is acceptable only for internal notes |
| Draft-then-approve write-back | Every write previewed and approved | Low-risk field updates such as "last contacted" earned auto-approval after a clean pilot |
12. Deliver It in Sixty Minutes
Spend minutes in proportion to risk. The permission model, the claim boundary and the write gate deserve more of the hour than the retrieval stack.
| Minutes | Phase |
|---|---|
| 0–8 | Workflow, decision owner, risk boundary, the five outputs by risk (section 1) |
| 8–15 | Sources and their permission models, the core records (section 3) |
| 15–25 | The end-to-end diagram, precompute versus ask versus write-back (sections 4 and 5) |
| 25–40 | Deep dive: CRM permissions and territory, structured versus semantic, claims and previews (sections 6 to 8) |
| 40–50 | Failure modes, evaluation slices, rollout gates (sections 9 to 11) |
| 50–60 | Close: spoken summary, trade-offs, week one |
The two-minute spoken answer:
I would not start with the model. I would start by clarifying the broken B2B (business-to-business) sales productivity workflow, who uses the system, what decision they need to make, and what risk we cannot automate. For Sales Copilot for Account Executives, I would design a permission-aware assistant around the workflow: AE prepares for account meeting, asks for account summary, opportunity risks, suggested discovery questions, email drafts, and CRM update suggestions. The architecture would ingest approved sources from systems like Salesforce/HubSpot, Gong/Zoom transcripts, emails/calendar, product docs, pricing/discount policy, customer support history, data warehouse, preserve metadata, freshness, and ACLs (access control lists), then use hybrid retrieval with permission filtering before generation. The LLM (large language model) would produce cited answers, show uncertainty, and escalate when evidence is missing or risk is high. Tool use would be allowlisted: read-only tools can run automatically, but any write-back or externally visible action needs preview and human approval. I would evaluate with SME-approved golden cases, citation accuracy, groundedness, permission red-team tests, task completion, latency, and cost. Rollout would be staged: offline prototype, shadow mode, read-only pilot, then limited approved actions with monitoring and rollback. The production goal is not a flashy demo; it is a trusted workflow assistant that is secure, auditable, and measurably improves the business process.
The lines that carry the round:
- "The five outputs sit on three sides of the risk boundary: read-only, draft-only, and approved write-back."
- "The brief is built before the meeting, as the rep, and re-checked at serve time. Precompute is an optimisation, never a permission model."
- "A count that includes a peer's territory is as much a leak as a forbidden document."
- "Risks come from CRM fields and transcripts the system fetched, never from what a typical deal looks like."
- "Every outbound claim traces to an approved-claims entry, and the verifier blocks, it does not warn."
- "Read tools run. Write tools preview, approve, and carry an idempotency key."
- "A 96.7 percent pass rate hid the six cases that mattered. Critical slices pass independently or nothing ships."
- "Fail closed on authorisation and approval. Degrade on everything else."
The follow-ups arrive in a predictable order.
| Follow-up | Answer |
|---|---|
| What if the model generates a fabricated customer fact? | By design and by test. Every fact in a brief carries a citation to a record or transcript the system fetched; the reasoning layer refuses to fill a missing field from model memory; the claim verifier blocks any outbound claim without an approved source. Test it with a golden set that includes accounts with deliberately sparse records and score groundedness per claim, not per answer. Online, monitor the unsupported-claim rate against baseline |
| How do you stop a rep seeing accounts outside their territory? | Mirror the CRM's sharing model, org-wide defaults, owner, role hierarchy, territory and field-level security, into attributes on every record; compile territory and role into the retrieval pre-filter; re-check on fresh attributes at serve time; invalidate snapshots on any territory change; hold structured counts to the same zero-violation gate |
| Why not let the copilot update the CRM directly? | A CRM write is an externally consequential action. Propose, preview the exact fields, approve, then write through the tool gateway with an idempotency key. After a clean pilot, low-risk fields may earn auto-approval; amounts, stages and closes never do on day one |
| How do you keep answers fast when the CRM is slow? | Precompute the snapshot on the calendar trigger and serve from cache; route common asks deterministically; parallelise the read-only calls that remain; cap agent steps; see section 13 |
| How would you know the eval suite is good enough? | Compare offline pass rates with online failure modes by slice. If a slice is small and critical, it gets its own gate. Add negative examples the model must refuse |
Repair the weak answers on the spot. "RAG (retrieval-augmented generation) with a vector database and ask GPT" becomes a workflow with a risk boundary and permission-aware retrieval. "Sales reps will review the drafts" becomes a claim verifier that blocks, with human review as the second line. "The model is too creative" becomes an eval and launch-gate problem with slice-based gates. "We'll add the CRM write later" becomes a tool gateway designed on day one with preview and approval.
Full Design 4 · 10 min — The complete, referenced write-up behind the other tabs. The sources for every tab live here.
13. Answer the Latency Pivot in Ten Minutes
The pivot after a good design is "sales users complain account prep takes 30 to 45 seconds." Answer it in the same sitting with the same architecture.
| Ask | Which tools are called? Serial or parallel? How many agent steps? Which data is required synchronously? Can account snapshots be precomputed? |
| Likely driver (confirm in traces) | Agent steps and serial tool calls |
| Weak move | Switch to a faster model without inspecting agent traces |
| Strong move | Trace the agent, cap steps, cache account data, parallelise read-only calls, precompute account summaries, route common requests to deterministic workflows |
| Path | user → deterministic intent route → account cache → parallel CRM/tool calls → summarisation → optional agent for ambiguous next steps |
| Trade-offs | Agent flexibility is useful, but common CRM operations should be deterministic and cache-backed |
| Metrics that prove it | Agent step count, tool latency, cache hit rate, timeout rate, cost per request |
| Recommendation | Replace the open-ended agent loop with a bounded execution graph |
The sixty-second line:
"Replace the open-ended agent loop with a bounded execution graph. Common CRM operations are deterministic and cache-backed; the agent handles only the ambiguous next step."
The snapshot lane in section 5 is that graph's first node. The design and the drill answer are the same thing.
Every strong cost answer is generated by four verbs in order. Measure, by tracing and attributing first. Route, matching model and path to risk. Bound, with limits on steps, tokens, top-k, timeouts and budgets. Cache safely, with tenant, permission and version in the key. Deliver it in six moves: frame the business impact, decompose the path, name the largest measured driver, fix safely, prove with before and after, prevent recurrence.
The sibling drill is a real-time sales assistant with a sub-3-second target during calls. It is a different system and lives in G16. Its answer is to precompute before the call, stream small suggestions during, and enrich asynchronously after.
14. Debug the Model-Regression Incident
The sheet maps this incident to G13, evaluation and release gating, because that is the lesson. It is walked here because the system is a sales copilot drafting outreach emails from CRM notes, product documentation and approved messaging. It is the failure the claim verifier in section 8 exists to prevent.
Detect. The company moved sales email drafting from llm_standard_v2 to llm_premium_v3 on 2026-07-08 at 09:00 after an offline eval showed better fluency and personalisation. Sales leaders then saw persuasive drafts claiming "SOC 2 Type II renewal completed in June 2026" and "average 34% support cost reduction". The SOC 2 claim was not yet approved for external use, and the ROI (return on investment) number came from an internal pilot. Offline evals had passed.
2026-07-08T12:16:44.921Z level=warn service=online-eval-monitor
  workflow=sales_email_draft model_route=llm_premium_v3 previous_model_route=llm_standard_v2
  unsupported_claim_rate=8.7% baseline=1.2% sample_size=430
  external_claim_policy_failures=37 severity=high

2026-07-08T12:17:03.108Z level=info service=eval-runner
  eval_suite=sales_copilot_release_gate version=eval_v14
  total_cases=120 pass_rate=96.7% release_gate=pass
  regulated_claim_cases=6 regulated_claim_pass_rate=83.3%
  missing_cases=[security_cert_pending,roi_internal_only,customer_logo_permission]

2026-07-08T12:17:11.339Z level=error service=claim-verifier
  trace_id=trc_eval_4402 request_id=req_sales_91902 tenant_id=acme
  generated_claim="SOC 2 Type II renewal completed in June 2026"
  claim_status=pending_approval approved_for_external_use=false
  retrieved_claim_doc_id=doc_security_roadmap_internal visibility=internal_only
  policy_action=should_block actual_action=warn_only
Contain. Roll back to llm_standard_v2. Restore block mode for external claims. Add review banners to every draft from the experiment.
Root cause. The eval suite over-measured writing quality and under-measured unsupported business claims. It had 120 cases and only 6 about regulated claims, and lacked cases for pending security certifications, internal-only ROI numbers and unapproved customer references. The model upgrade increased persuasive extrapolation. The policy evaluator had been switched from block to warn-only during the experiment to reduce false positives, so the risky drafts went through. Three changes lined up. A stronger model. A weaker gate. A suite blind to the slice that mattered.
Prevent. Build a claim-level eval suite with labelled approval status. Add slice-based release gates and require zero critical failures on regulated claims. Monitor the unsupported-claim rate online against baseline. Add negative examples where the model must refuse to use internal-only claims. Never run a policy evaluator in warn-only mode for external drafts, whatever the false-positive rate.
The strong answer in the room:
"The failure is an eval and launch-gate problem. The suite passed at 96.7%, but it had only six regulated-claim cases and the online unsupported-claim rate jumped to 8.7%. I would roll back the model route, restore blocking for external claims, add claim-level evals for security, ROI, and customer-logo claims, and require critical slices to pass independently before release."
The weak answer is "the model is too creative, make the prompt stricter and ask reps to review."
| Criterion | Strong Signal | Weak Signal |
|---|---|---|
| Problem framing | Identifies eval coverage regression | Says model is "too creative" only |
| Telemetry interpretation | Reads slice pass rates, unsupported claim rate, policy action | Cites aggregate pass rate only |
| Root-cause reasoning | Connects model route, weak evals, warn-only policy | Blames prompt alone |
| Production debugging | Compares offline/online failures by slice | Manually edits one draft |
| Security/privacy awareness | Notes legal/commercial risk of unsupported claims | Treats as style issue |
| Mitigation quality | Rollback, block mode, claim-level gates | Adds generic human review only |
| Communication clarity | Explains why evals missed critical slice | Says "evals passed" defensively |
Level calibration
On this design the levels separate on how long the boundary around the brief holds, through territory changes, model upgrades and release gates, not on how well the brief reads.
| Level | Sounds like | Missing |
|---|---|---|
| Senior | Builds the brief on the calendar trigger as the rep, caches it on account plus permission signature and rechecks access at serve time. Sends counts and ID lookups to fixed CRM operations and prose to hybrid search, blocks unapproved claims and previews every CRM write. | The release proof: claim-level slices that gate on their own, what keeps the verifier in block mode, and who signs off each source and write tool. |
| Staff | Adds a claim-level suite where regulated claims pass independently, so 96.7% over 120 cases cannot hide 83.3% on six, plus an online unsupported-claim monitor against baseline. Security owns the permission red team, and rollout runs from one CRM connector and three reps through shadow mode and a read-only pilot before drafts and write-back. | How the claim, pricing and permission contracts hold as tenants, sources and model routes multiply, and which writes ever earn a narrower automated route. |
| Principal | Runs the approved-claims playbook, versioned pricing policy, CRM sharing mirror and model routes as control-plane releases, each with an owner, a canary and a rollback, so nobody quietly flips the verifier to warn-only again. Makes IdP group mapping, per-tenant keys and per-connection vault credentials the contract every new customer onboards through, and keeps the in-call assistant a separate G16 system. | The allowed snapshot staleness, the cost per workflow budget and whether a field such as last contacted ever earns auto-approval wait on the customer's pilot data and risk appetite. |
Key Takeaways
- The workflow is the pre-meeting hour, and its five outputs sit on three sides of a risk boundary: read-only, draft-only, approved write-back.
- Requirements are stated so a test can fail them: four must-haves as the launch gate, a non-goals list, and a component owner for each.
- Every source carries its own permission model, and the CRM's is the richest: org-wide defaults, owner, role hierarchy, territory, sharing rules, field-level security.
- One diagram splits control plane from data plane and keeps three lanes apart: precompute, ask and gated write-back.
- The brief is built before the meeting, as the rep, cached on the rep's permission signature and re-checked at serve time.
- Identity comes from the customer's own IdP, CRM sharing rules are mirrored into attributes, and a structured leak is held to the document leak's gate.
- A router sends counts and lookups to fixed CRM operations and prose to search, and risks are reasoned from fetched fields, never model memory.
- Every outbound claim traces to an approved-claims entry, the verifier blocks rather than warns, and every write is previewed and approved.
- Authorisation and approval fail closed; everything else degrades visibly with a label.
- The release gate has slices, and the critical slices pass independently or nothing ships.
- Rollout runs from offline prototype through shadow mode and read-only pilot to draft-only actions behind approval.
- The hour is spent on permissions, claims and the write gate, with the spoken answer and eight lines ready.
- The latency pivot is answered by the bounded execution graph the design already has.
- The regression incident is an eval and launch-gate failure: stronger model, weaker gate, suite blind to the slice that mattered.
Check Yourself
- Which of the five outputs may be written back without approval on day one? None. Summary and risks are read-only, questions and drafts are the rep's to send, and every CRM update is previewed and approved through the tool gateway.
- Why is a precomputed snapshot re-checked at serve time? A snapshot is a materialised view and can outlive a permission change; a rep moved off a territory must not read the morning's snapshot in the afternoon.
- What does the CRM permission mirror carry that a document ACL (access control list) does not? Org-wide defaults, owner, role hierarchy, territory assignment and sharing rules for records, plus field-level security, so forecast amount or any other restricted field can be hidden from roles that cannot see it.
- Why prefer fixed CRM operations over generating queries from natural language? A generated query can invent fields or touch every row; a reviewed set of operations bounds what can happen and is the same allowlist the tool gateway enforces.
- Where may an outbound claim come from, and what happens otherwise? Only from the approved-claims playbook; the claim verifier blocks the draft, it does not warn.
- What hid the regression in the incident? A 96.7 percent aggregate pass rate over 120 cases, with only six regulated-claim cases passing at 83.3 percent, and a policy evaluator switched to warn-only.
- What is the likely driver when account prep takes 30 to 45 seconds, and the fix? Usually agent steps and serial tool calls; trace first to confirm, cap steps, cache and precompute the account, parallelise read-only calls, route common asks deterministically, and replace the open loop with a bounded execution graph.
- What is the answer to "what if the model fabricates a customer fact"? Citations per claim to fetched records, refusal to fill missing fields from model memory, a blocking claim verifier, per-claim groundedness scoring on a sparse-record golden set, and an online unsupported-claim monitor.
References
Fact-check sources (checked 27 Sep 2026)
- FDE (Forward Deployed Engineer) problem-decomposition question bank — reusable practice cases for ambiguous enterprise problems
- Control Who Sees What (Salesforce Help) — record access starts from org-wide defaults; FLS controls fields
- Field-Level Security (Salesforce Help) — hiding fields such as amount by profile or permission set
- AWS KMS cryptography essentials (envelope encryption) — what per-tenant data keys do and do not protect
- Stripe API reference: Idempotent requests — idempotency keys stop a retried write from running twice
- OWASP GenAI LLM01:2025 Prompt Injection — treating content as data lowers but does not stop injection
- OWASP GenAI LLM06:2025 Excessive Agency — gate write tools outside the model
- G05 Deep Dive, latency pivot — agent steps and serial tool calls are the likely driver, to confirm in traces